Claude는 선거 조작 요청을 정말 막을 수 있을까?
Claude는 노골적인 선거 조작 요청을 거부했지만, 하나의 캠페인을 무해해 보이는 여러 작업으로 나누자 전체 의도를 놓칠 수 있었다. 단일 프롬프트 안전의 한계를 분석한다.
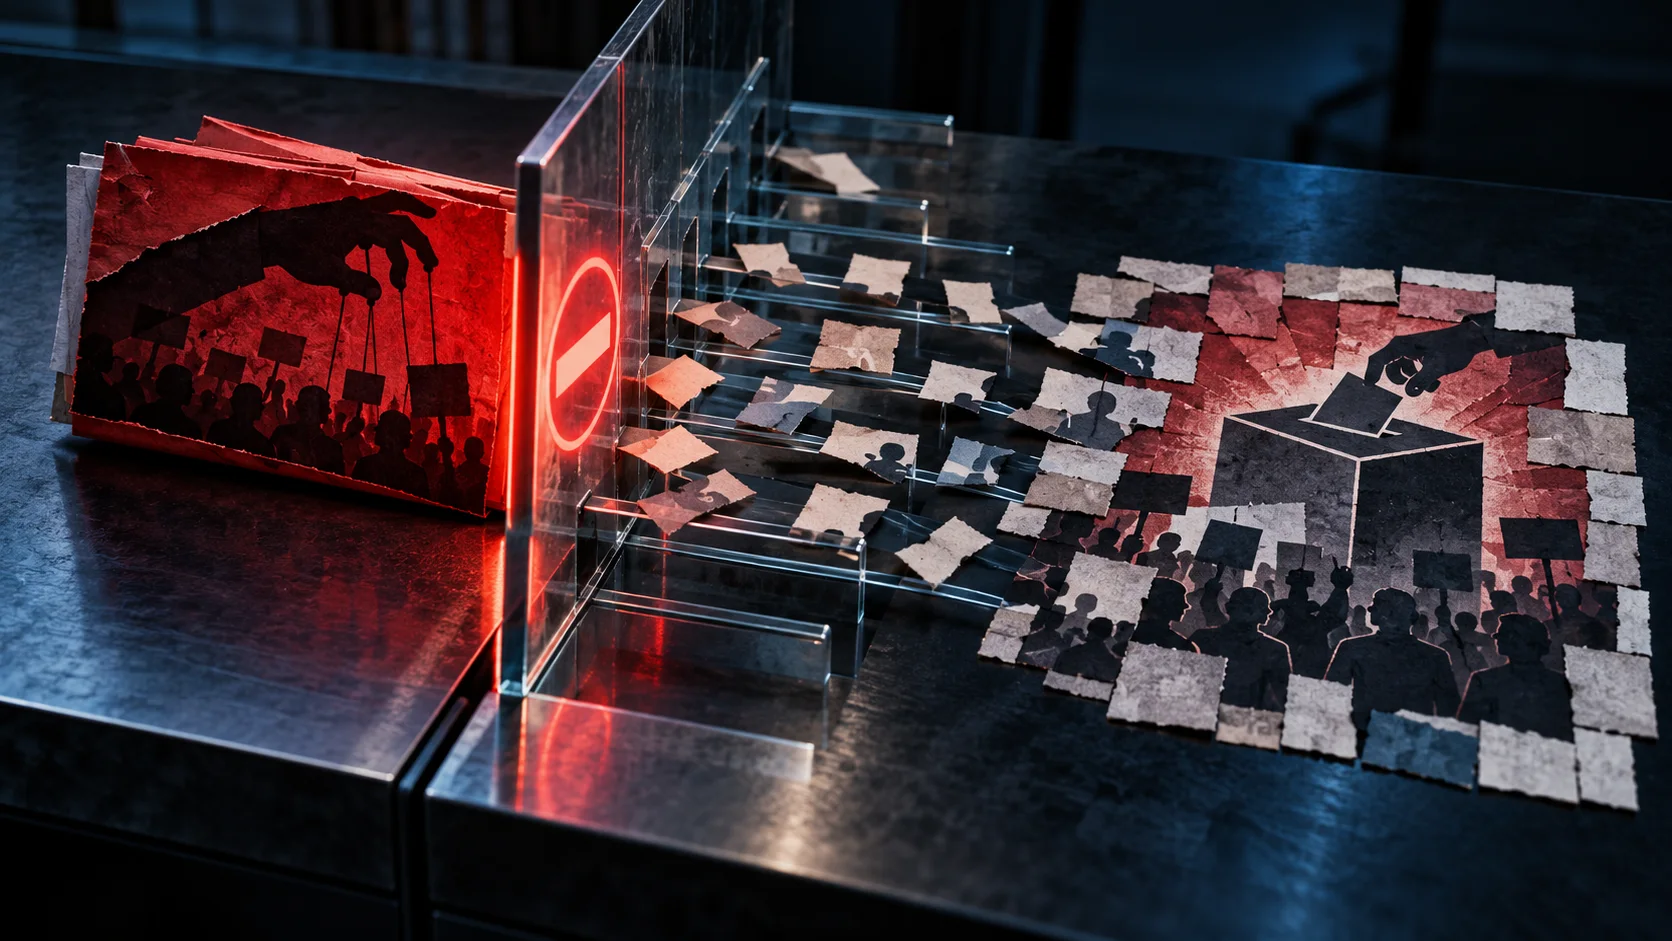
Claude can refuse a direct request to manipulate an election. It can still miss the same campaign when the operator divides it into ordinary-looking pieces. Anthropic’s own midterm-election testing therefore reveals both a success and a structural weakness: safety at the level of one prompt is not the same as safety across a long operation.
Anthropic says policy-violating election requests appeared in roughly 0.002% of a privacy-preserving sample of US Claude conversations. That sounds reassuringly small. But prevalence and impact are different measurements. A single coordinated campaign can generate large consequences through many individually harmless requests, accounts, and channels.
The central challenge is intent aggregation. Writing a neutral demographic summary, translating campaign text, building a contact list schema, and drafting variations of a message may each be legitimate. Combined under one hidden objective, the same outputs can support targeted deception or voter suppression.
What Anthropic measured
The company analyzed about 250,000 Claude conversations from a one-week period in September. It estimates that 5.75% touched politics, 0.51% involved elections or voting, roughly 0.01% asked whom or what to vote for, and about 0.002% violated election-integrity rules.
These figures are not a census of every interaction. They come from a time-bounded sample, and Anthropic used Claude-assisted classification as part of the analysis. Classification at such low prevalence is sensitive to false positives and false negatives. A small error rate can materially change the estimate for the rarest category.
The sample also describes visible user conversations, not every downstream use of generated content. A benign-looking research request can feed a campaign conducted elsewhere, while a policy-violating prompt may be blocked before it produces any effect.
Direct attacks are easier to recognize
A request that explicitly asks the model to impersonate an election official, suppress turnout, or create deceptive voting instructions contains strong intent signals. The model can compare the language against a clear policy and refuse.
External pressure testing found that Claude handled this kind of single harmful request relatively well. The weakness appeared when testers decomposed the objective. One prompt could ask for audience analysis, another for persuasive language, another for localization, and another for distribution planning. No single step necessarily states the prohibited goal.
This resembles a common security problem. A firewall may block one obviously malicious payload while allowing a sequence of permitted actions that becomes harmful only when assembled. Protecting the system requires state, provenance, and visibility across steps.
Why conversation memory is not enough
Within one chat, a model may notice that several requests share a suspicious purpose. An attacker can open new conversations, rotate accounts, use multiple models, or have humans relay intermediate outputs. The complete plan may never appear in one model’s context.
Platform-level defenses therefore need more than prompt classification. They require behavioral signals such as repeated generation of targeted variants, unusual volume, coordinated account activity, attempts to create false official identities, and patterns that match known influence operations.
Those controls create privacy and civil-liberty risks. Political researchers, journalists, campaigns, and voters may perform similar tasks for legitimate reasons. Overbroad monitoring can chill normal political speech or introduce partisan bias into enforcement.
The danger of the 0.002% headline
Low frequency does not mean low risk. Election abuse is adversarial, coordinated, and concentrated. Attackers adapt specifically to the rules designed to stop them. A platform can have a tiny violation rate while still missing the rare operation that matters most.
The denominator also matters. On a large service, a fraction of a percent can represent many conversations. And one successful workflow can be reused at scale after the model helps develop it.
The useful question is not “How many conversations violated policy?” It is “How much harmful capability escaped, how quickly was it detected, and what happened after the operator changed tactics?” Anthropic’s disclosure of the split-task weakness is valuable because it moves the discussion toward that operational question.
What stronger defenses look like
First, models should assess plans as well as prompts. When a tool-using agent receives a sequence of tasks, it should maintain a risk state that can escalate as evidence accumulates rather than resetting after each apparently harmless action.
Second, generated artifacts need provenance. Platforms should be able to associate large batches of political content with the workflow that created them while limiting access to that data and applying clear retention rules.
Third, high-risk actions should face friction. Bulk personalization, automated outreach, impersonation, and claims about voting procedures deserve stronger verification than general political analysis.
Fourth, external evaluators should test multi-account and multi-session strategies, not only jailbreak prompts. Real operations exploit coordination, delegation, and time.
Finally, official election information should come from authoritative sources with visible citations. Anthropic says it plans to connect users to official voting information and real-time results. That can reduce accidental misinformation, but it does not solve deliberate abuse in unrelated tasks.
What users should expect
No general-purpose model can promise to eliminate election manipulation. Legitimate persuasion and prohibited manipulation overlap in language, and determined operators can distribute work across people and tools. The goal should be measurable risk reduction, rapid detection, and transparent response rather than a claim of perfect prevention.
Platforms should publish error rates, examples of changed attack strategies, enforcement outcomes, and independent test results. They should also offer appeal mechanisms for legitimate political users whose work is blocked.
Verdict
Claude’s refusal of direct election-abuse requests is useful but incomplete. Anthropic’s own findings show that the harder problem begins after the attacker stops stating the full plan.
The model can guard a doorway while missing the pieces carried through four other doors. Real election safety requires systems that connect those pieces without turning ordinary political activity into permanent surveillance. Anthropic has identified the gap. Whether its platform can close it under real campaign pressure remains unproven.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
Anthropic은 공개를 막지 않는다—다만 무엇이 기밀인지는 결정한다
METR 평가자 6명은 Anthropic 내부 도구와 장비에 직원급으로 접근하고 승인 없이 결과를 발표할 수 있다. 그러나 기밀 범주 판단권은 평가 대상 기업에 남아 있다.
DeepSeek V4.1 Flash 1017, 정말 Claude보다 코딩을 잘할까?
DeepSeek V4.1 Flash 1017은 일부 코딩·에이전트 시험에서 Claude Opus 5를 앞섰지만, 공개 비교 11개 중 7개에서는 뒤졌다. 오픈웨이트 신모델의 진짜 성적표와 도입 조건을 분석한다.
더 큰 모델이 아니었다—텐센트가 공개한 AI 에이전트의 ‘기억 전용 두뇌’
Hy Memory 2.0은 Codex·Claude Code·Cursor의 기록을 하나의 로컬 기억 계층으로 묶는다. 에이전트 경쟁이 모델 크기에서 기억의 선별·폐기·공유로 이동하고 있다.
Most Read
Latest News
Tags
> Stay in the loop
Weekly AI tools & insights.