Whiteboard Turns AI-Generated Code Into a Reviewable System Map
The open-source Code OSS desktop app links agent-drawn architecture, semantic diffs, and decision logs back to source code. Its bet is that understanding—not generation—is now the coding bottleneck.
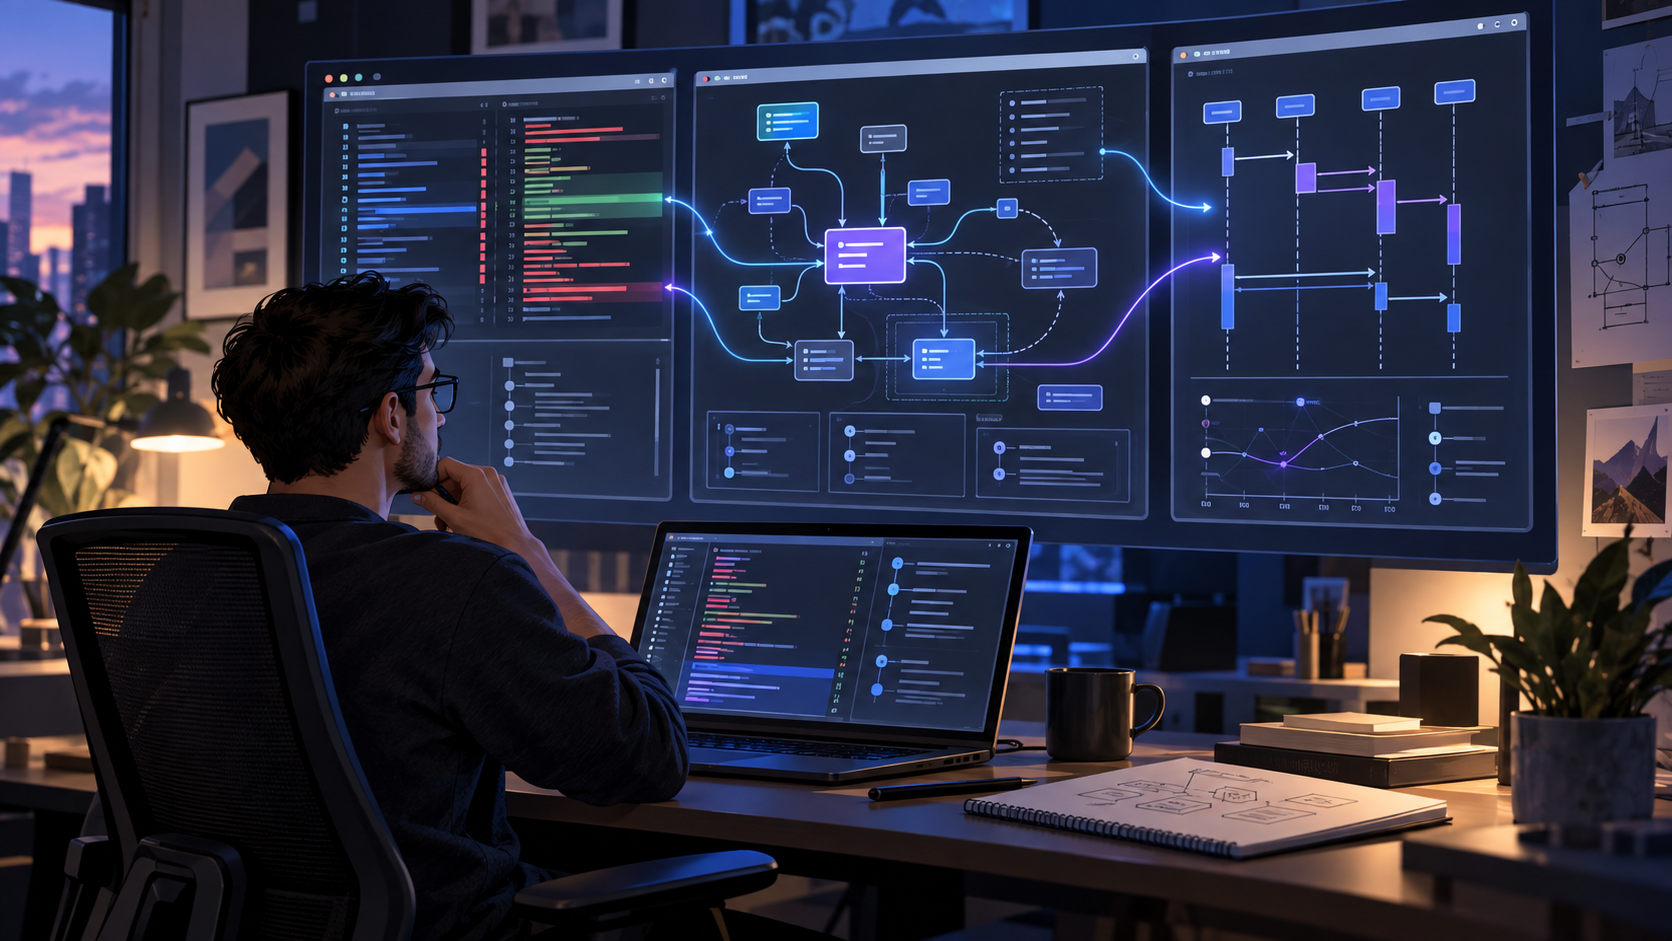
Whiteboard is an open-source desktop application for understanding code produced by coding agents. Instead of presenting only a line-by-line diff, it lets Claude Code, Codex, and compatible tools draw system diagrams, explain decisions, and connect those explanations to the relevant source files. The project is built on Code OSS and released under the MIT license.
The September 25 launch discussion reached 240 points and 94 comments on Hacker News at our check. Its GitHub repository showed 599 stars and 25 forks. Those numbers measure early developer attention, not proof that the product improves review quality or works equally well across large repositories.
What happened
Whiteboard’s developers released a review-focused workspace that combines a code editor with an agent-accessible canvas. A reviewer can ask an agent to compare a branch with the main line, draw a sequence or entity-relationship diagram, explain how a requirement became an implementation, and link a visual element to the source that supports it.
The application includes a semantic diff viewer written around Rust-based syntax analysis. Its defaults can summarize a large new function as pseudocode and collapse changes such as tests or documentation so a reviewer can focus on architecture. A WASM plugin system can alter those presentation rules.
A decision log addresses a different gap. The agent can link its execution trace to choices represented on the canvas, separating explicit user requirements from decisions the agent made while implementing them. Whiteboard currently emphasizes explanation and review rather than direct file editing. It runs against a local checkout; the team says a hosted collaboration product is planned while self-hosting will remain available.
Why it matters
Coding agents can create more code than one engineer can comfortably inspect as raw patches. That shifts the constraint from generation to comprehension. A reviewer needs to know which components changed, why an API was shaped a certain way, where data crosses a trust boundary, and which assumptions were not specified by a human.
Visual explanation can compress that search. A sequence diagram can show a request path before the reviewer opens ten files. A decision log can identify the branch where an agent chose a cache, retry policy, or telemetry event without explicit direction. Linking each explanation back to source keeps the canvas from becoming a detached slide deck.
The more important product idea is escalation. Automated checks can cover formatting, types, tests, and known bug patterns. Human attention can then concentrate on requirements, architecture, privacy, operational risk, and whether the change should exist at all. Whiteboard is trying to become the workspace for that higher-level judgment.
Evidence
The public repository exposes the code, license, privacy documentation, telemetry reference, contribution guide, and examples. The launch post describes a Code OSS foundation, source-linked canvas elements, an AST-aware diff viewer, trace-backed decision logs, and local-repository operation. Those claims can be inspected in the project rather than accepted from a promotional screenshot alone.
The team says the product is already used for architecture- and specification-level reviews and cites users at companies including Salesforce and Modal. That is a founder-reported adoption signal, not an independent customer study. No public controlled evaluation shows that Whiteboard reviewers find more defects, review faster, or retain a better mental model than reviewers using an editor and ordinary pull request.
The architecture also creates maintenance questions. Shipping a Code OSS-based desktop app gives Whiteboard editor navigation and language-server support, but it leaves the project responsible for integrating upstream security and feature changes. The repository’s own documentation acknowledges this ongoing work.
Practical takeaway
Teams should test Whiteboard on a change they already understand. Ask the agent to draw the request path, list autonomous decisions, and connect each claim to source. Then compare the result with the actual diff and tests. The useful evaluation questions are concrete:
- Did the map expose an important dependency or trust boundary?
- Could every important claim be traced to code?
- Did summarization hide a test, migration, or failure path that mattered?
- Did the decision log distinguish a user requirement from an agent assumption?
- Could another engineer update the system after reading the review?
Treat the diagrams as navigation aids, not authority. Review the underlying code, run the project tests, and inspect generated artifacts before approval. For sensitive repositories, read the privacy and telemetry documents and validate network behavior against the team’s policy.
Limitations
Whiteboard is early. Its documentation says direct file editing is not the main workflow, multi-repository review is limited, and shared reviews do not yet update live after they are sent. Semantic summarization can reduce noise, but any system that hides or rewrites a diff can also hide the exact line that changes behavior.
Agent-authored explanations may be plausible but wrong. Source links reduce that risk only if the reviewer follows them. A canvas can also become another generated artifact that must be reviewed, adding work rather than removing it on small changes.
Final verdict
Whiteboard targets a credible new bottleneck: teams can merge agent-generated code faster than they can understand the systems they are creating. Its strongest design choice is not visualization by itself; it is the attempt to tie diagrams and decisions back to executable source. The project is worth testing on architecture-heavy changes, with the understanding that review evidence still ends in code, tests, and human judgment.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
Agentic Coding's New Bottleneck Is Review Evidence, Not More Parallelism
Whiteboard visualizes intent, Archify maps systems, and TODO Flow preserves task and review state. Together they show a tool category forming around one problem: proving what coding agents changed and why it is safe to merge.
CLM-8B Chooses the Next Action Instead of Writing the Next Sentence
Contrastive Language Models separate state and action encoders so repeated candidate actions can be cached and ranked quickly. The release is promising, but its headline coding scores describe verifier-assisted pipelines—not a standalone coding agent.
AI Science Agents Need an Evidence Ladder, Not a Discovery Score
Anthropic's ART result, Google's AI co-scientist, and published laboratory validations show a common pattern: agents can widen hypothesis search, but experiments determine what survives.
Tags
> Stay in the loop
Weekly AI tools & insights.