OpenAI's Decisions API Turns Model Judgment Into Typed Application Data
The public beta returns probabilities, fixed choices, and rubric scores from text or images, giving developers a narrower and faster primitive than open-ended generation.
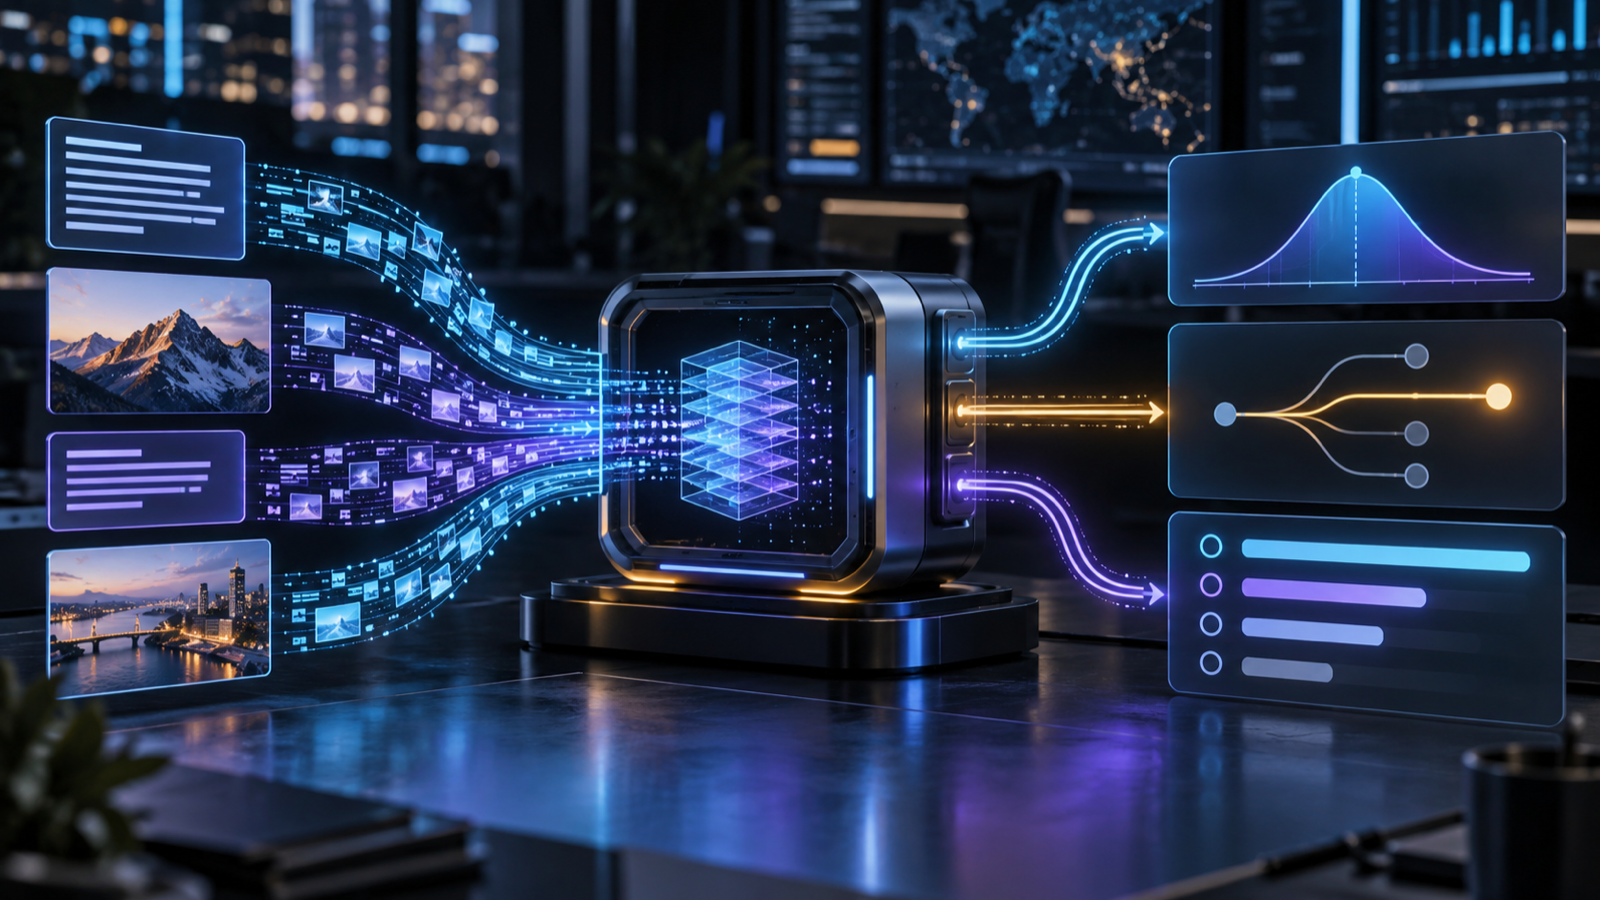
OpenAI has opened the Decisions API as a public beta, adding a dedicated endpoint for applications that need a judgment rather than prose. The official guide defines three outputs: a probability that a condition is true, one choice from a developer-supplied set, or a probability-weighted score against ordered levels. Requests can use text, images, or both as shared evidence.
That narrow contract is the point. A support queue does not necessarily need an essay about where a ticket belongs; it needs a department. A marketplace inspection system may need the probability that a product is visibly damaged. A moderation workflow may need a severity score whose thresholds are controlled by application policy. The API makes those outputs first-class instead of asking developers to extract them from a general response.
OpenAI says the endpoint returns typed answers about ten times faster than the Responses API. That is the company’s comparison, not an independent benchmark, and latency will still depend on input size, network conditions, and workload. At launch, the documentation lists gpt-6-luna as the only supported model and describes the service as beta, with general availability expected later.
What happened
The dedicated POST /v1/decisions endpoint accepts one shared input and one or more named questions. A predicate returns a probability from zero to one. A choice returns one of the permitted values plus probabilities across the choices. A score uses ordered levels and returns their probability-weighted average, so the result can fall between two rubric levels.
The answer name is echoed in the response, which lets one input support several decisions without relying on array position alone. The guide also documents refusals as a separate answer type. Current SDK minimums are listed for Python, JavaScript, Go, Ruby, and Java.
OpenAI draws an explicit boundary around the feature. Developers who need an arbitrary JSON object should use Structured Outputs with the Responses API. Applications that want a model to request a tool should use function calling. Decisions is for a small set of judgment shapes, not a replacement for general generation.
Why it matters
For production teams, the important change is architectural. Model output becomes a measurable input to conventional software. A probability can be calibrated and thresholded. A fixed choice can be checked against an allowlist. A score can feed prioritization while the application retains authority over what happens next.
That separation can reduce a common failure mode in AI products: asking one prompt to interpret evidence, invent a schema, explain itself, and trigger an action. With a typed decision, the model supplies an estimate and ordinary code owns the policy. A developer can route low-confidence cases to people, log distributions, compare versions, and change thresholds without rewriting every downstream integration.
The multimodal input matters too. Damage inspection, document triage, creative review, and catalog classification often mix images with short text. A single evidence bundle and several named questions may be easier to evaluate than separate free-form prompts whose wording and parsing drift independently.
Evidence and community reaction
The official documentation is the primary evidence for the feature set, current model, endpoint, and claimed speed difference. Public developer attention was immediate: the Hacker News submission had 199 points and 91 comments when checked at 1:00 p.m. Malaysia time on October 7. GeekNews also surfaced the release that morning. Those numbers indicate interest, not product quality.
The discussion focused on calibration, pricing, reproducibility, and how the endpoint differs from constrained generation. Those are the right questions. A probability-looking number is not automatically a calibrated probability. Teams must test whether events assigned roughly 0.8 confidence actually occur about 80 percent of the time on their own data. They must also examine performance by language, image conditions, customer group, and rare but costly cases.
Practical takeaway
Start with a decision that already has labeled examples and a clear human policy. Reserve a test set that was not used to write instructions. Measure accuracy, confusion by class, calibration, latency, and cost. Then select thresholds according to the harm of false positives and false negatives rather than choosing 0.5 by habit.
Keep the model answer separate from authorization. A high probability can recommend a route; it should not silently grant account access, deny a benefit, prescribe care, or execute an irreversible action. Store the input version, question instructions, model, answer distribution, threshold, and final action so incidents can be reconstructed.
Use abstention deliberately. The API may return a refusal, but application-level uncertainty is broader than refusal. If the top two choices are close, an image is poor, or the input differs from the validation set, route the case to a safer path. A useful decision system is defined as much by what it declines to automate as by what it handles quickly.
Limitations
The service is a public beta with one listed model. Interfaces, pricing, behavior, and availability may change. OpenAI’s ten-times-faster statement needs workload-specific verification. The documentation demonstrates output forms but does not establish calibration for every domain.
Typed output also does not remove bias, prompt injection, ambiguous evidence, or distribution shift. Images and text can contain instructions that should be treated as data, not authority. High-stakes uses require domain review, monitoring, appeal paths, and appropriate human oversight.
Bottom line
The Decisions API packages model judgment as a smaller production primitive: predicate, choice, or score. That could make classification and routing systems easier to test and govern than prose-first workflows. The strongest implementation will not be the one that trusts the probability most. It will be the one that validates calibration, owns policy in code, records the evidence chain, and gives uncertain cases somewhere safe to go.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
AI Decision Models Are Becoming a Control Plane, Not a Chat Feature
OpenAI's typed Decisions API and Strands' local Decider 2B point to a layered architecture where models estimate, application policy decides, and uncertain cases escalate.
Strands Decider 2B Brings Agent Routing to a Small Open Model
The two-billion-parameter release targets fast local decisions inside agent systems, offering an inspectable alternative for experiments where a large generative model is unnecessary.
The Next AI Efficiency Gain Is Amortizing Work Across the Whole System
Dust, Quail, and OpenRig attack different layers, but share one idea: useful AI systems get cheaper and more reliable when they reuse structure across training signals, data operations, and agent work.
Tags
> Stay in the loop
Weekly AI tools & insights.