AI Decision Models Are Becoming a Control Plane, Not a Chat Feature
OpenAI's typed Decisions API and Strands' local Decider 2B point to a layered architecture where models estimate, application policy decides, and uncertain cases escalate.
Two releases visible in developer communities this week approach the same production problem from opposite directions. OpenAI’s hosted Decisions API returns a predicate probability, fixed choice, or ordered score from text and images. Strands Decider 2B is a small open model intended for local decision work inside agent systems.
They are not equivalent products. One is a managed multimodal endpoint currently tied to one listed model; the other is an open checkpoint and ecosystem component that transfers deployment to the user. Their shared significance is architectural: model judgment is separating from model generation.
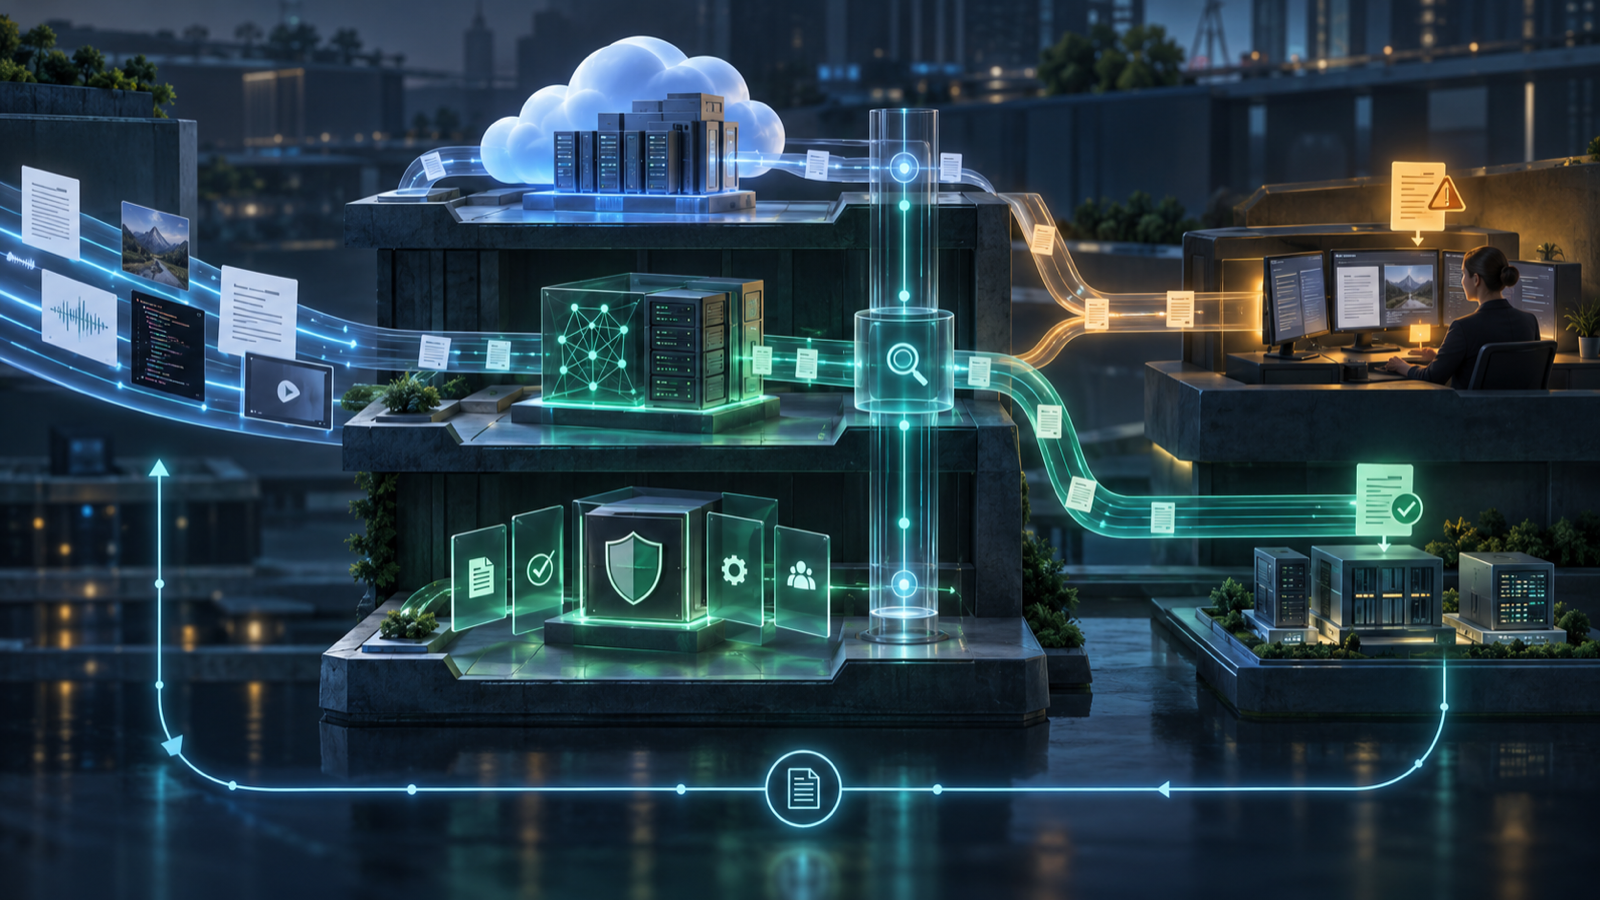
That creates a potential AI control plane. Evidence enters through retrieval, forms, sensors, or agent state. A model estimates relevance, category, severity, or the next route. Application policy converts the estimate into an action, an abstention, or human review. The model does not need to write the customer-facing answer, and the answer model does not need to own authorization.
Why a separate decision layer is emerging
General models are convenient because one endpoint can summarize, classify, extract, plan, and write. In production, that flexibility creates coupling. A prompt change intended to improve explanations can alter routing. A model upgrade can shift tool use. An instruction that asks for both a category and a rationale gives the prose generator influence over a machine action.
A constrained decision interface reduces the output surface. OpenAI exposes three typed shapes. Strands focuses a smaller model on choice-like work. Both make it easier to ask a measurable question: given this evidence and choice set, how often does the system select the correct route, and what happens when it is unsure?
The distinction also enables model tiering. A local model might handle routine agent routing. A hosted multimodal service might inspect inputs that need image understanding. A frontier reasoning model might resolve only ambiguous cases. Deterministic rules can still override all three where policy is explicit.
Probability is useful only when it is tested
A probability creates more operational options than a bare label, but it can also create false precision. Calibration asks whether predictions with a stated confidence correspond to observed frequencies. The modern neural-network calibration literature shows that accuracy and calibration are different properties; a model can rank classes well while being systematically overconfident.
Production teams therefore need reliability diagrams, Brier scores or other proper scoring rules, and error analysis by subgroup and input condition. Calibration can drift after a model change or when live traffic differs from the test set. A threshold chosen for one market, language, camera, or support taxonomy should not be assumed safe everywhere.
The decision should also reflect consequences. If a false positive merely sends a ticket to the wrong internal queue, automation can tolerate more uncertainty. If it denies access, removes income, or initiates an irreversible operation, a similar error rate may be unacceptable. Policy owns that tradeoff, not the model.
A three-layer production architecture
The first layer is evidence handling. It retrieves only needed context, treats user-supplied instructions as untrusted data, records provenance, and checks whether the input is complete enough to evaluate.
The second layer is estimation. A decision model produces a distribution, choice, or score under a pinned version and named rubric. The service should be replaceable: a hosted endpoint, local checkpoint, conventional classifier, or rule can compete behind the same evaluation harness.
The third layer is policy and action. Ordinary code applies thresholds, permissions, rate limits, and escalation. High-impact actions require stronger evidence or human confirmation. Every action links back to the model output and evidence version so an incident can be reconstructed.
This separation mirrors the NIST AI Risk Management Framework’s emphasis on governing, mapping, measuring, and managing risk across the system rather than treating the model as the whole product.
Hosted and local are complementary
OpenAI’s service offers a managed interface, multimodal input, SDK integration, and a reported speed advantage over its general Responses API. The beta status, single supported model, external data path, and vendor dependency are real constraints.
Strands Decider 2B offers local control, inspectability, and independent serving. The user must manage hardware, inference software, security, evaluation, scaling, and updates. A small local model may also be less capable on unfamiliar inputs.
A sensible system can use both. Routine low-risk routing can remain local; difficult multimodal cases can call a hosted service; the most uncertain outcomes can reach a person. The important property is not allegiance to one deployment model. It is a stable contract and evidence trail across them.
Practical implementation checklist
Define the decision in operational language before choosing a model. Create mutually exclusive labels or an ordered rubric. Collect representative examples, including ambiguous and adversarial cases. Split evaluation data before tuning instructions.
Compare rules, a conventional classifier, a local decision model, and a hosted endpoint. Measure end-to-end outcomes rather than component accuracy alone. Include latency, infrastructure cost, privacy exposure, escalation volume, and the downstream cost of a wrong route.
Add abstention as a normal output. Monitor class prevalence, confidence distributions, override rates, and outcome quality. Re-evaluate after any model, prompt, tool, or taxonomy change. Preserve a rollback path. For consequential decisions, supply notice, human review, and an appeal mechanism appropriate to the domain.
Limitations
The two releases are new and primarily documented by their creators. Their public discussion signals interest, not independent validation. OpenAI’s speed claim is vendor-reported. Strands’ open and local positioning does not prove superiority to rules or existing small classifiers.
Decision interfaces can also hide reasoning that reviewers need. Explanations generated after a choice may be plausible rather than causal. Auditing should rely on inputs, outputs, versions, tests, and observed outcomes—not on a fluent rationale alone.
Bottom line
AI products are beginning to treat judgment as infrastructure. The useful pattern is simple: models estimate, software policy decides, and uncertainty escalates. OpenAI’s Decisions API and Strands Decider 2B make different tradeoffs within that pattern. Teams should benefit if they preserve the separation—because once a model both estimates the world and authorizes the action, a convenient feature has quietly become an ungoverned control plane.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
OpenAI's Decisions API Turns Model Judgment Into Typed Application Data
The public beta returns probabilities, fixed choices, and rubric scores from text or images, giving developers a narrower and faster primitive than open-ended generation.
Strands Decider 2B Brings Agent Routing to a Small Open Model
The two-billion-parameter release targets fast local decisions inside agent systems, offering an inspectable alternative for experiments where a large generative model is unnecessary.
The Next AI Efficiency Gain Is Amortizing Work Across the Whole System
Dust, Quail, and OpenRig attack different layers, but share one idea: useful AI systems get cheaper and more reliable when they reuse structure across training signals, data operations, and agent work.
Tags
> Stay in the loop
Weekly AI tools & insights.