Amazon Researchers Use Compression to Explain Why ML Agents Generalize
A new study treats a short strategy passed between agents as an information bottleneck, testing why repeated benchmark optimization does not always overfit.
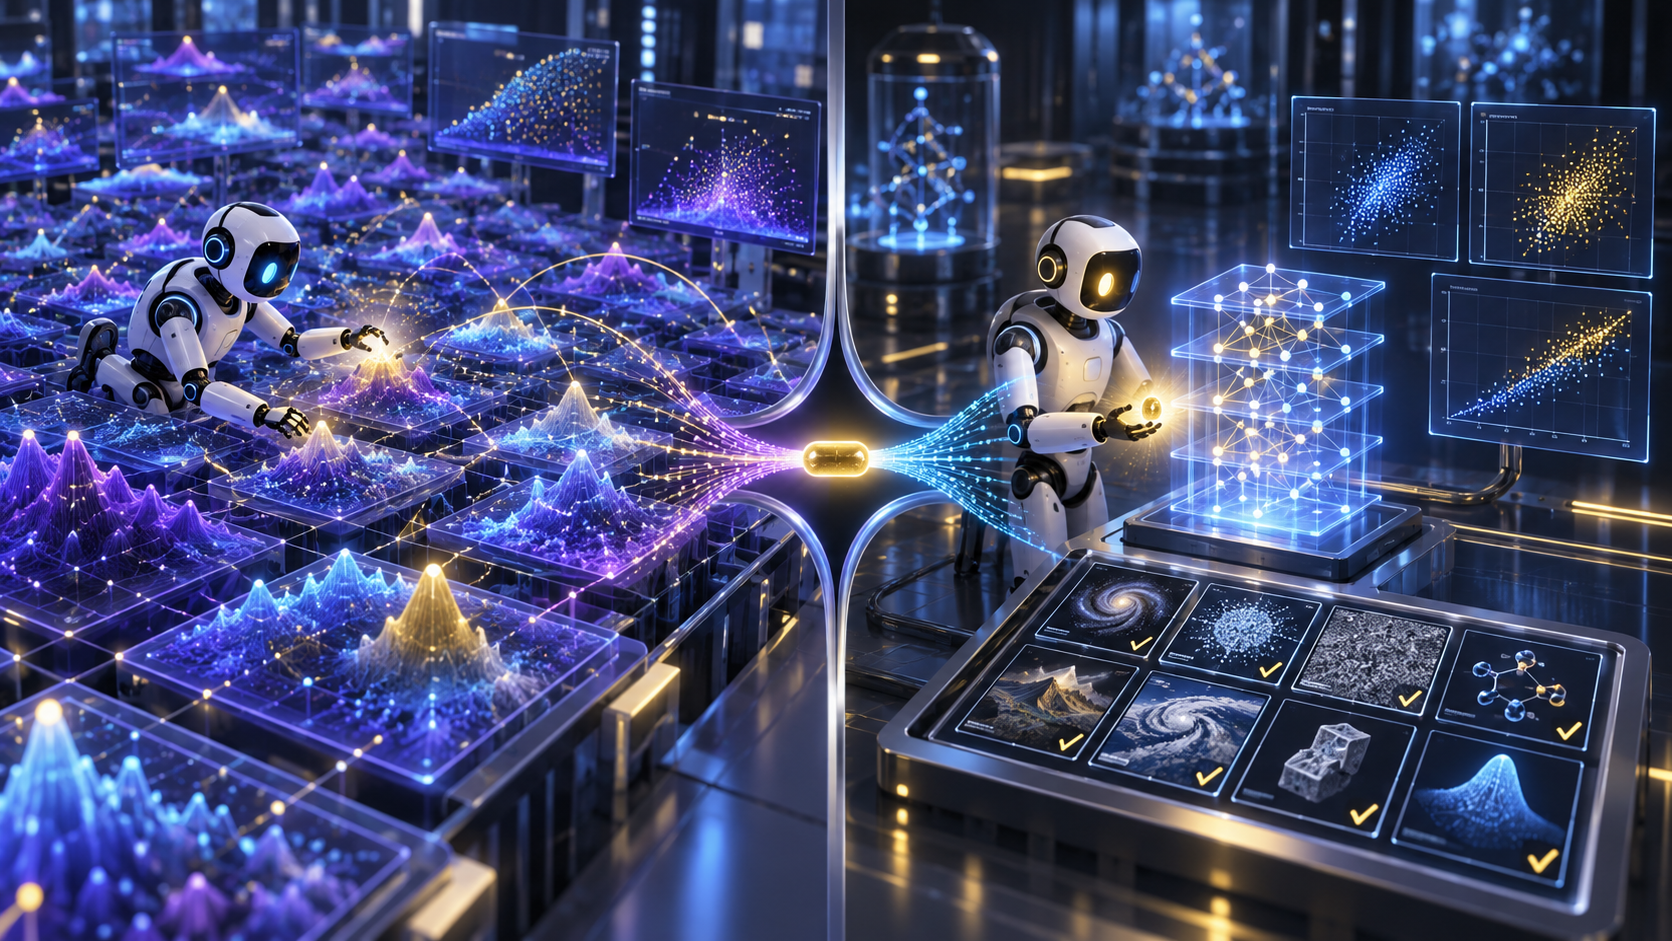
Amazon researchers have proposed an information-theoretic explanation for a puzzle in machine-learning research: teams repeatedly optimize against familiar benchmarks, yet improvements often transfer to freshly collected test sets instead of collapsing as textbook overfitting predicts.
Their paper, “What fits (into few tokens) doesn’t overfit,” uses LLM research agents to make the process experimentally controllable. The central test asks an explorer agent to optimize on a validation set, compress its final strategy into a short message, and hand that message to a fresh implementer agent. If the compact strategy retains performance on unseen data, the result supports the idea that successful methods generalize because their essential recipe carries too little information to memorize the benchmark.
The Amazon Science article was posted September 10 and entered Hacker News on September 14. The discussion had 115 points and 65 comments at our check.
What happened
The researchers distinguish the long transcript of experimentation from the final transferable method. An explorer may inspect thousands of results, but its surviving recommendation can be small: architecture family, optimizer, schedule, preprocessing, and a few hyperparameters.
A knowledgeable implementer can expand that compressed description because it already knows standard tools and conventions. This matters in the theoretical argument. Shared background knowledge does not need to encode the validation examples, so the problem-specific message can remain short.
The study resets the implementer and limits the explorer’s message through a token bottleneck. It then compares the transmitted strategy on held-out data. This turns an otherwise historical question about the behavior of an entire research community into a repeatable agent experiment.
Why it matters
Benchmark contamination is a major concern in modern AI. Public test sets influence architecture choices, prompts, training data, and product decisions. Repeated contact should make a benchmark less trustworthy as an estimate of future performance.
The compression view offers a conditional reason for optimism. If the final strategy is genuinely compact relative to the amount of evaluation data, it cannot secretly encode every validation answer. Strong performance is more likely to reflect reusable structure.
The condition is essential. A short natural-language message can point to a large external artifact, rely on contaminated pretrained knowledge, or invoke an implementation whose defaults were themselves tuned on the benchmark. Token count is not automatically the same as effective information.
Evidence
Amazon’s article explains the experimental logic, the connection to Occam’s razor, and the role of a knowledgeable decoder. The linked arXiv paper contains the formal treatment and empirical design. Together they are a primary research source rather than a third-party summary.
The public discussion raised reasonable objections about what counts as compression and whether a powerful language model can reconstruct benchmark-specific choices from its pretraining. Those concerns do not negate the experiment, but they define the boundary of its interpretation.
The paper does not prove that every benchmark improvement generalizes or that leaderboard reuse is safe. It offers a mechanism that can be measured in controlled settings.
Practical takeaway
Agent teams can use the explorer-to-implementer pattern as an evaluation tool:
- Give the explorer access to a development benchmark and a fixed experiment budget.
- Require a compact final recipe with no result tables, examples, checkpoints, or hidden files.
- Reset context and let a fresh agent implement the recipe.
- Evaluate once on a separately governed holdout.
- Compare the full-transcript handoff with several message-size limits.
If performance disappears when the transcript is removed, the apparent method may depend on fragile search history. If a short recipe survives across datasets and implementations, the evidence for a reusable insight becomes stronger.
This is also relevant to human review. A concise method forces researchers to state what actually changed. It makes ablations easier and reduces the risk that an undocumented prompt tweak or cached artifact carries the result.
Limitations
EgoistAI reviewed the Amazon Science explanation, the linked paper record, and the public discussion but did not reproduce the experiments. The headline result depends on task selection, agent capability, information limits, and what resources the fresh implementer can access.
Compression alone does not establish scientific value. A short strategy can generalize poorly, exploit a shared artifact, or produce a tiny but statistically insignificant improvement. Fresh test sets, error analysis, multiple seeds, and domain transfer remain necessary.
Research agents also introduce execution variance. Tool failures, nondeterministic training, and differences in environment can dominate small effects. A robust replication should record code, data versions, compute budgets, and all external dependencies.
Final verdict
The study gives researchers a useful way to test whether an agent discovered a transferable idea or merely accumulated benchmark-specific adjustments. Its strongest contribution is the experimental bottleneck, not a blanket claim that overfitting has been solved. Short, independently reimplemented strategies deserve more trust—but only when data governance and hidden information channels are controlled.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
dbt Charts Turns Agent-Built Dashboards Into Auditable YAML
dbt Labs open-sourced a declarative dashboard language designed for chat-driven analytics, with validation, Git workflows, and multiple render targets.
Claude Fable 5.1 May Have Solved a 370-Year-Old Cipher—The Verification Is the Real Story
A Vals AI experiment reports that Claude Fable 5.1 decoded Thomas Urquhart's Cyphral Distich. The result is compelling, but the repeatable key matters more than the headline.
Signal's Phone-Numberless Registration Work Moves Zero-Knowledge Proofs Into Account Creation
Signal Android commits and public discussion indicate a new registration path using zkgroup credentials, extending earlier plans for paid phone-numberless accounts.
Tags
> Stay in the loop
Weekly AI tools & insights.