Feature-Flagged LLM Rollouts: Ship Model Changes Without Losing Control
Treat model upgrades like production code: route by cohort, shadow traffic, enforce kill switches, and separate prompt, model, retrieval, and tool changes.
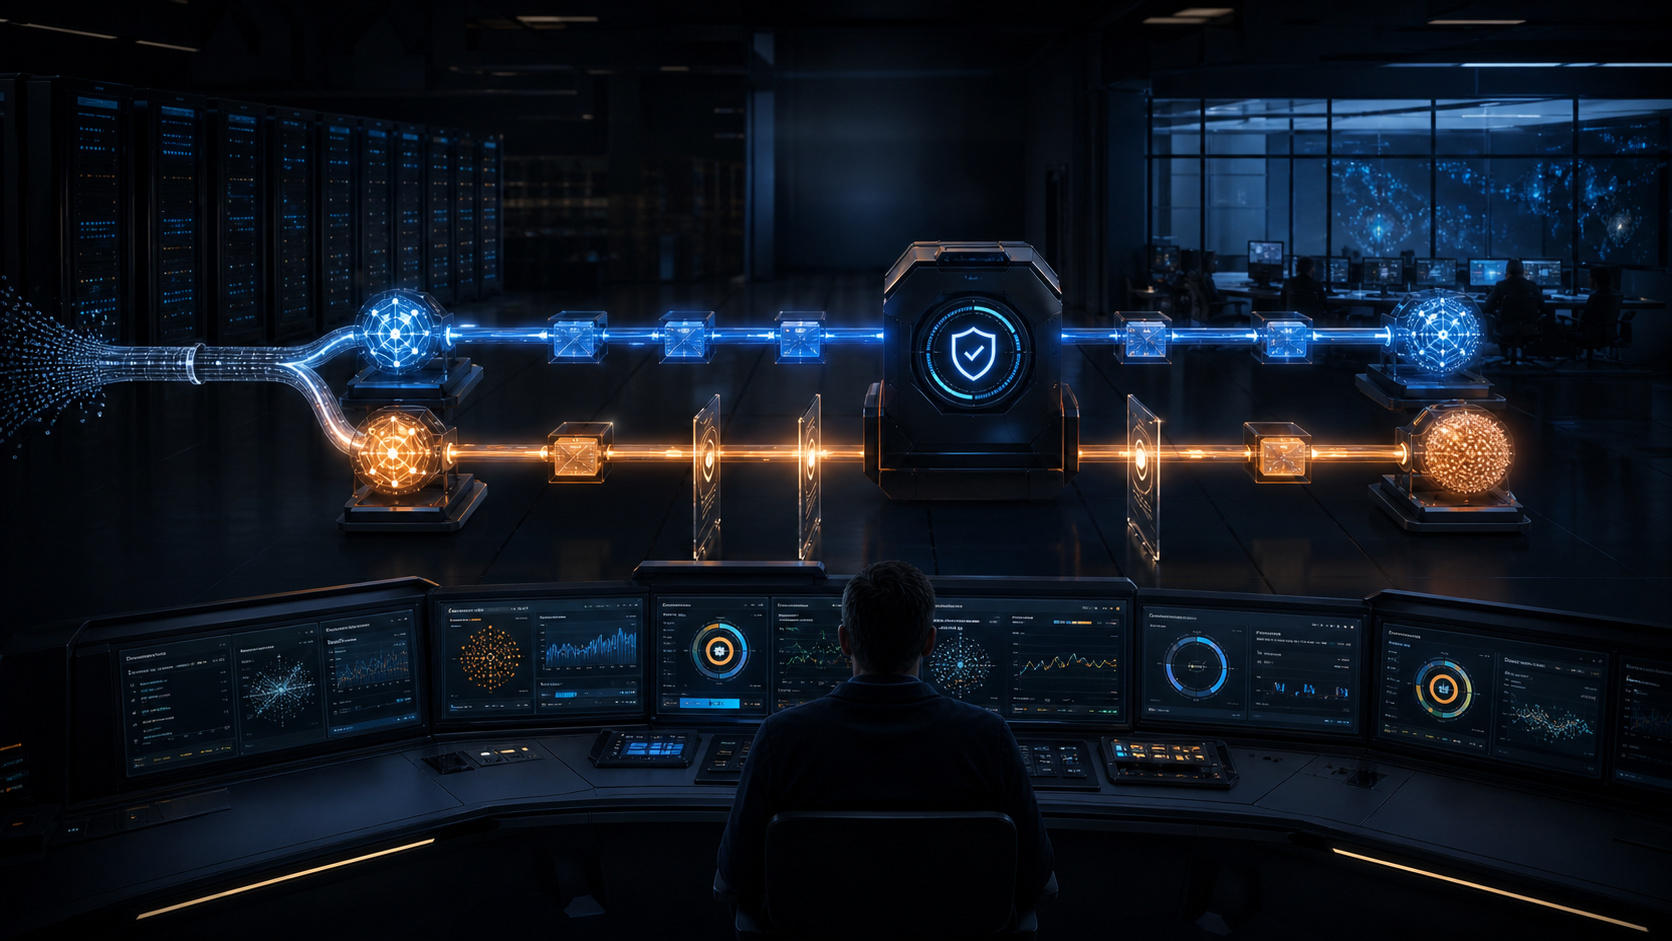
Changing an LLM model name can alter reasoning, tool selection, latency, cost, refusal behavior, and output structure at once. A standard binary deployment treats all of those shifts as one irreversible bet.
Feature-flagged LLM rollouts make the model path a controlled runtime decision. You can expose a new configuration to a measured cohort, compare it with the incumbent, and stop traffic without rebuilding the application.
Flag the Whole Runtime Configuration
Do not create a flag that changes only model. Define a versioned bundle containing the model, system prompt, sampling parameters, tool schemas, retrieval settings, response parser, safety policy, and fallback chain.
Store the bundle ID on every trace. When quality drops, “the new model failed” is not a useful diagnosis if the deployment also changed chunking and tool descriptions.
Keep flags server-side. Client flags can leak experimental settings and allow users to select configurations that were never approved for their data or workload.
Choose Cohorts Deliberately
Start with replay and shadow traffic, where the new runtime receives production-shaped inputs but cannot trigger external side effects. Compare schema validity, factual support, tool-call accuracy, latency, tokens, and policy outcomes.
Then canary low-risk live requests. Cohorts should be stable and explainable: internal users, test tenants, a deterministic percentage, or workloads with read-only tools. Avoid random assignment on every request; a multi-turn conversation should not switch models halfway through unless migration is designed explicitly.
Exclude regulated, high-value, or irreversible workflows until evidence supports expansion.
Define Promotion Gates Before Launch
Write the success criteria first. A rollout might require no regression on a sealed evaluation set, a minimum structured-output success rate, bounded p95 latency, and human-reviewed quality on disagreement samples.
Use guardrail metrics as well as averages. A lower mean cost does not justify a sharp increase in catastrophic tool errors. Track outcomes by language, task type, context length, and tool because aggregate numbers hide local failures.
Promotion should be an explicit state transition: shadow, one percent, ten percent, half, general availability. Record who or what approved each step.
Build a Real Kill Switch
A kill switch must work when the main deployment pipeline is impaired. Keep it in a highly available control plane with a safe cached default. Operators should be able to route new requests back to the last known-good bundle in seconds.
Decide what happens to in-flight work. Read-only requests may retry on the old runtime. Side-effecting agents need operation receipts and idempotency keys before any replay. Never assume a timeout means the action did not happen.
Separate Experiment Flags From Permanent Policy
Temporary rollout flags accumulate quickly. Give each an owner, creation date, review date, and removal condition. Once a configuration is fully adopted, make it the default and delete the branch.
Long-lived routing rules—such as sending images to a multimodal model or sensitive workloads to a regional endpoint—belong in a policy engine, not a forgotten experiment flag.
The best model rollout is intentionally boring. Version the entire behavior surface, gather evidence without side effects, expand by stable cohort, and preserve a fast path back to reality.
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
pgvector Can Return 4 of Your 10 Matches—Where Did the Rest Go?
A filtered vector search can quietly starve your AI app of evidence. pgvector has a fix, but builders need to measure recall and latency before trusting it.
Agent Memory Consolidation Scheduling: When to Merge, Summarize or Forget
Your agent doesn't need more memory — it needs a maintenance schedule. Here's how to build merge, summarize, and decay policies that keep long-term agents sharp instead of senile.
LLM Output Schema Evolution: Migrating Producers and Consumers Without a Flag Day
Your JSON schema will change. Here's how to evolve LLM output contracts safely — with dual readers, shadow validation, and staged rollouts instead of a risky big-bang cutover.
Most Read
- 1 Kimi K3.1 Pro: China's Open-Weight Model Just Caught the Frontier
- 2 OpenAI Is Buying the Bottleneck: Can Orchestra Bio Cut a 15-Year Drug Timeline?
- 3 1,068 Tokens Per Second: Can Mercury 3 Change How LLMs Generate Text?
- 4 Same Price, Better Coding: How Good Is DeepSeek V4.1 Flash 1017?
- 5 Used OpenCode? Should You Rotate Your API Key After the Console Breach?





Latest News
- Claude Code Left Secrets in 1,122 GitHub Files—Check This Setting
- Gemini Omni 1.2 Flash Makes 15-Second Video Cheaper—Then Comes the Edit
- GPT-6 Cyber Can Build Exploits—But Builders Face a Different Test
- 1,122 GitHub Files Exposed Secrets—What Did “Don't Ask Again” Save?
- Gemini Omni 1.2 Flash Offers $1.05 Clips—What Does That Buy You?
- GPT-6 Cyber Hits 48.5% on ExploitGym—Who Gets the Keys?
Tags
> Stay in the loop
Weekly AI tools & insights.