Deterministic AI Agent Incident Replay: Debug the Trace, Not the Vibe
Agent incidents are hard to reproduce because models, tools, and external state all move. Capture the right boundaries and replay becomes an engineering tool.
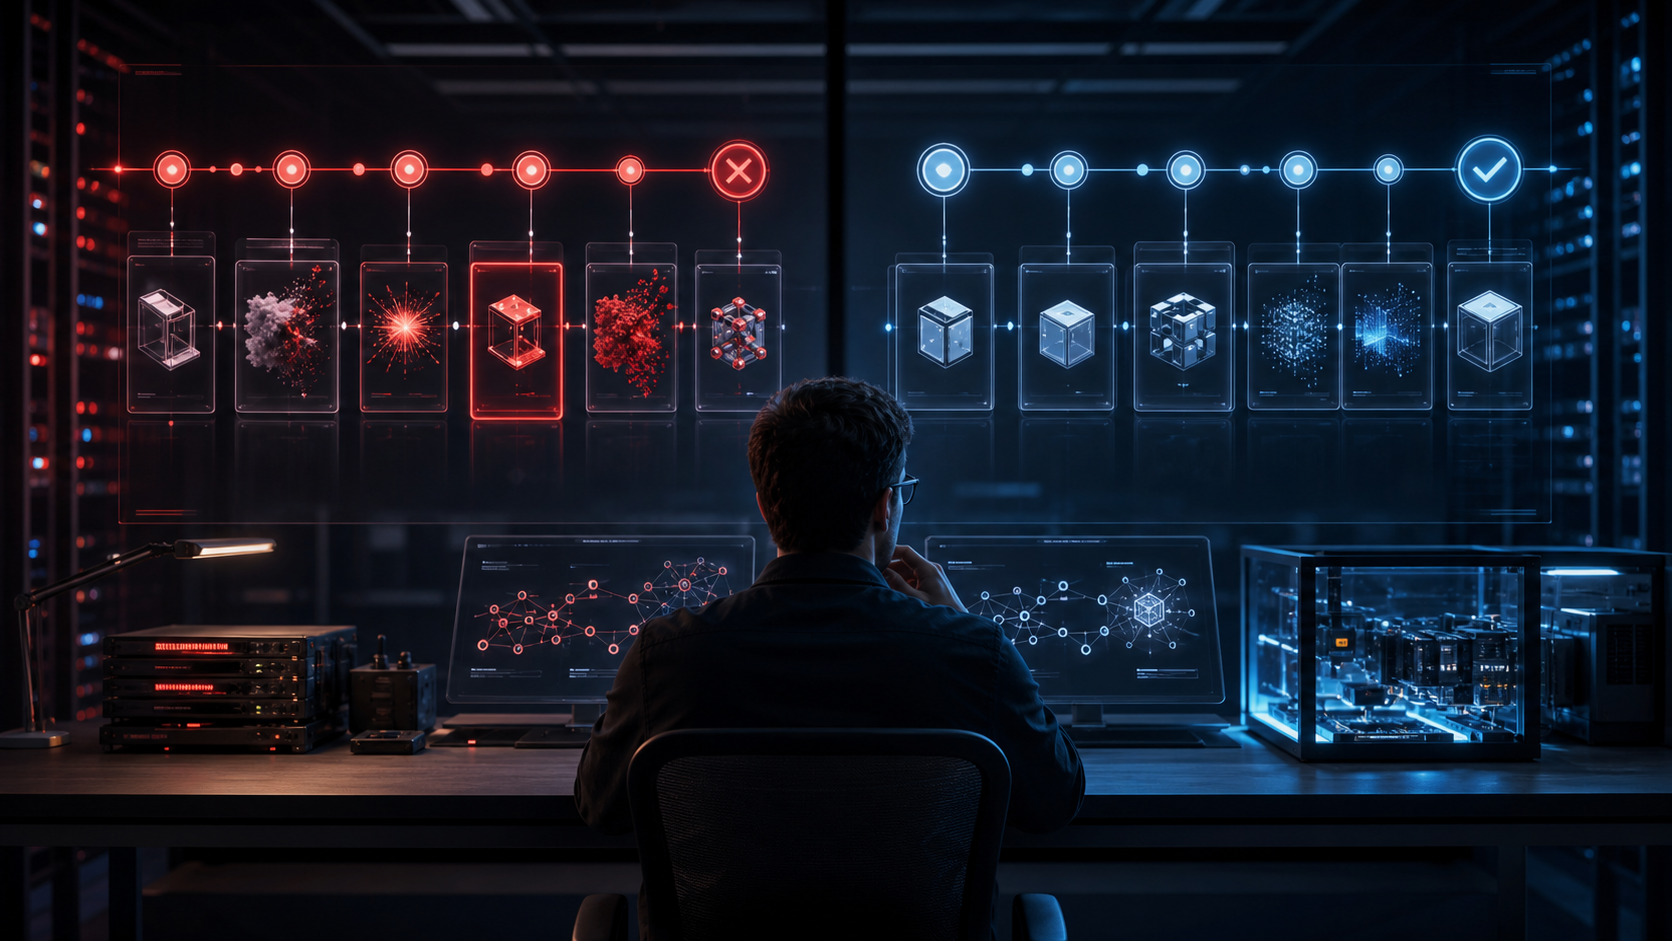
The production agent deleted the wrong draft. The team copies the prompt into a playground, reruns it, and gets a perfect answer. Incident closed? Not remotely.
The original failure depended on a specific model version, hidden system instructions, retrieved documents, tool schemas, database state, timing, and perhaps a timeout that occurred after the write committed. Replaying only the visible prompt reproduces a story, not the system.
Deterministic incident replay starts by capturing boundaries.
Record the Execution Envelope
For each model turn, store the model identifier, sampling parameters, full message roles, tool definitions, structured response, token usage, latency, and provider request ID. Store a hash of large or sensitive payloads and keep the encrypted source under a separate retention policy.
For each tool call, capture normalized arguments, authorization decision, idempotency key, start and finish times, result status, and a redacted response fixture. Mutating calls also need precondition and postcondition evidence.
{
  "span": "tool.delete_draft",
  "trace_id": "tr_92a1",
  "input_hash": "sha256:...",
  "authority": "drafts:delete:one",
  "idempotency_key": "draft-883-delete",
  "precondition": { "draft_id": "883", "version": 17 },
  "outcome": "success",
  "postcondition": { "exists": false }
}
If you cannot explain what the agent believed before the side effect and what changed after it, you do not have a replayable trace.
Virtualize Nondeterminism
Network calls, clocks, random IDs, search results, and changing databases make exact reproduction impossible unless they are intercepted. During replay, replace those dependencies with recorded fixtures.
Provide a virtual clock. Seed local random generators. Return the original tool results in the original order. Map generated IDs to stable replay IDs. Freeze retrieved documents at the versions used during the incident.
The first replay mode should be strict: the model receives the same inputs and tools receive fixtures without touching real systems. This answers whether the reasoning path can be reproduced safely.
Compare Semantics, Not Raw Text
Model output may differ in punctuation while producing the same action. Evaluate structured decisions:
- Which tool was selected?
- Which object and business key were targeted?
- What authority was asserted?
- Which validation condition passed or failed?
- Did the state machine move to the same state?
Canonicalize JSON before diffing and classify changes as harmless text drift, decision drift, tool drift, or side-effect drift. The last two deserve the highest severity.
Use Three Replay Modes
Fixture replay returns recorded model and tool outputs to verify orchestration deterministically. It is fast and ideal for regression tests.
Model replay calls the current or historical model with recorded tool fixtures. It reveals whether prompt, model, or decoding changes alter decisions.
Shadow replay runs the current stack against a sanitized copy of state while blocking external writes. It tests the full decision process under more realistic conditions.
Never begin incident analysis by replaying mutations against production. Read-only fixtures should be the default, with synthetic IDs and a hard network denylist for human-facing endpoints.
Turn the Incident Into a Regression
The final artifact is not a video of the failure. It is an executable test with assertions:
expect(run.toolCalls).not.toContainEqual(
  expect.objectContaining({ tool: "delete_draft", draftId: "883" })
);
expect(run.finalState).toBe("approval_required");
expect(run.authorityViolations).toHaveLength(0);
Keep the smallest fixture that still reproduces the decision. Mask personal data, tokens, and confidential content. Record which production symptom the fixture represents and which control now prevents recurrence.
Measure Replay Quality
Track the percentage of incidents with complete traces, fixture resolution success, reproduction rate, decision-drift rate across model upgrades, and time from alert to executable regression.
Replay infrastructure has a compounding payoff. It converts mysterious agent behavior into inspectable state transitions, lets teams test model upgrades against real failures, and makes postmortems evidence-based.
You may never make a generative system perfectly deterministic. You can make the environment around its decisions deterministic enough to debug—and that is the difference between observing an incident and learning from it.
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
pgvector Can Return 4 of Your 10 Matches—Where Did the Rest Go?
A filtered vector search can quietly starve your AI app of evidence. pgvector has a fix, but builders need to measure recall and latency before trusting it.
Agent Memory Consolidation Scheduling: When to Merge, Summarize or Forget
Your agent doesn't need more memory — it needs a maintenance schedule. Here's how to build merge, summarize, and decay policies that keep long-term agents sharp instead of senile.
LLM Output Schema Evolution: Migrating Producers and Consumers Without a Flag Day
Your JSON schema will change. Here's how to evolve LLM output contracts safely — with dual readers, shadow validation, and staged rollouts instead of a risky big-bang cutover.
Most Read
- 1 Kimi K3.1 Pro: China's Open-Weight Model Just Caught the Frontier
- 2 OpenAI Is Buying the Bottleneck: Can Orchestra Bio Cut a 15-Year Drug Timeline?
- 3 1,068 Tokens Per Second: Can Mercury 3 Change How LLMs Generate Text?
- 4 Same Price, Better Coding: How Good Is DeepSeek V4.1 Flash 1017?
- 5 Used OpenCode? Should You Rotate Your API Key After the Console Breach?





Latest News
- Claude Code Left Secrets in 1,122 GitHub Files—Check This Setting
- Gemini Omni 1.2 Flash Makes 15-Second Video Cheaper—Then Comes the Edit
- GPT-6 Cyber Can Build Exploits—But Builders Face a Different Test
- 1,122 GitHub Files Exposed Secrets—What Did “Don't Ask Again” Save?
- Gemini Omni 1.2 Flash Offers $1.05 Clips—What Does That Buy You?
- GPT-6 Cyber Hits 48.5% on ExploitGym—Who Gets the Keys?
Tags
> Stay in the loop
Weekly AI tools & insights.