CLM-8B Chooses the Next Action Instead of Writing the Next Sentence
Contrastive Language Models separate state and action encoders so repeated candidate actions can be cached and ranked quickly. The release is promising, but its headline coding scores describe verifier-assisted pipelines—not a standalone coding agent.
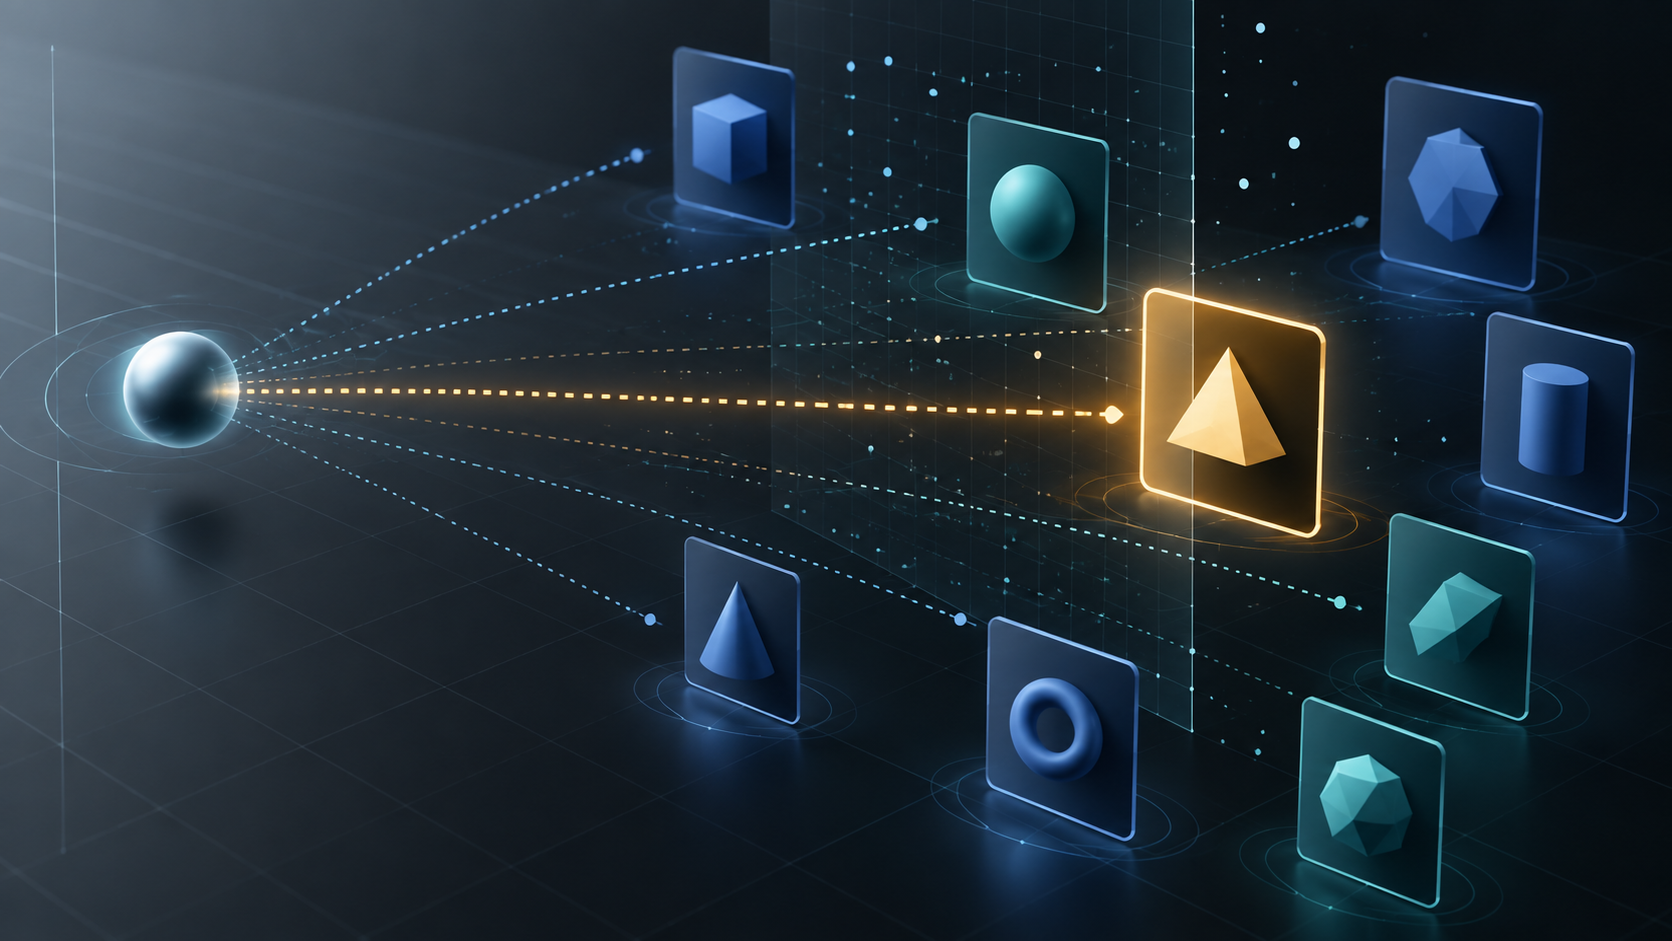
Contrastive-LM released CLM-8B, an open model system designed to score a fixed set of actions against a current state. It is not primarily a text generator. A developer supplies the situation and candidate actions—tools, routes, answers, or game moves—and the system returns a ranking or typed probability distribution.
At our September 25 check, the new GitHub repository had 913 stars and 69 forks. The maintainers released code under Apache 2.0, model and data artifacts on Hugging Face, serving tools, a local playground, fine-tuning instructions, and evaluation commands.
What happened
CLM uses separate encoders for states and actions. Each is built from a frozen Qwen3-8B backbone plus a trainable projection head. Contrastive training pulls a correct state-action pair closer in the embedding space and pushes incorrect pairs apart. At inference time, the system embeds new state text, compares it with candidate-action embeddings, and chooses the closest match.
That separation enables caching. If an agent repeatedly chooses among the same tools, departments, or game moves, it can embed those action descriptions once. Only the changing state requires a fresh encoder pass. The repository exposes a TypeSafe-compatible typed-question API and a lower-level rank operation for free-form candidates.
The maintainers say CLM-8B was pretrained on roughly 60 million Nemotron question-answer pairs, mid-trained on 30 million synthetic hard negatives, and post-trained on one million agent trajectories. They report performance comparable with Jev across selected computer-use, gaming, and tool-calling tests with as much as ninefold lower latency in their setup.
Why it matters
Many agent steps are selection problems disguised as generation. A router chooses one tool. A support system chooses one queue. A search pipeline chooses which documents to inspect. A best-of-N workflow chooses one candidate solution. Asking a large generative model to write a fresh paragraph for each decision can be slow, expensive, and difficult to calibrate.
A dedicated action scorer can make the control plane smaller and more inspectable. The candidate set is explicit. Probabilities can be logged. Actions can be versioned and cached. A team can define a reject or escalation threshold rather than treating fluent prose as certainty.
The architecture is especially attractive when actions recur across many states. Its advantage shrinks when every candidate is unique, a state is extremely long, or the task requires inventing a new action that is absent from the set.
Evidence
The repository contains runnable serving code, evaluation scripts, held-out task lists, downloadable heads, and reproduction commands. That is stronger evidence than a launch claim without artifacts. The reported coding results, however, require precise interpretation.
For DeepSWE and Terminal-Bench 2.1, other models generated multiple candidate solutions. Fine-tuned CLM heads then acted as verifiers that selected a candidate. The reported 81.6% DeepSWE result covered 31 successes in 38 held-out tasks; the 87.6% Terminal-Bench result covered a 30-task held-out set. The figures are not CLM-8B solving the full coding benchmark from scratch, and they are not a single-pass score on the entire public benchmark.
The speed figures are also workload-dependent. Caching is most useful when the candidate actions are reused. Hardware, batch size, sequence length, cache temperature, and comparison model configuration affect latency. The repository says the agentic-verifier latency was measured on an H100, while the playground screenshot refers to a Qwen3-8B encoder on an RTX 4090.
Practical takeaway
Use CLM first where the action space is closed and errors can be audited: tool routing, triage, policy categories, retrieval reranking, or selecting among independently generated candidates. Build a local evaluation set with real states, correct actions, ambiguous cases, and an explicit “none of the above” path.
Measure more than accuracy. Track calibration, abstention, latency with cold and warm caches, action-set changes, and the cost of a wrong route. If a candidate description changes, invalidate its cached embedding. If two actions overlap semantically, clarify the criteria instead of expecting the model to infer organizational policy.
For best-of-N coding, preserve the generator candidates, verifier scores, execution results, and chosen patch. A verifier should not replace tests. It should prioritize what to test or review.
Limitations
The model can only rank what it is given. Missing actions, misleading descriptions, or adversarial state text can produce a confidently wrong selection. Long states are truncated at the configured model limit unless operators raise it and accept the memory cost.
The public results come from the project’s maintainers and use relatively small held-out task sets for the headline coding experiments. Independent replication across different generators, repositories, and action distributions is still needed. Training data and synthetic hard-negative construction may also shape which errors the model finds easy.
Final verdict
CLM-8B is interesting because it treats agent control as contrastive selection rather than miniature essay writing. The cacheable state-action design is technically coherent, the code and artifacts are public, and the verifier results justify further testing. The honest claim is narrower than the headline numbers: CLM may be a fast decision layer inside an agent system, not a replacement for the agent, environment, or independent validation around it.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
Agentic Coding's New Bottleneck Is Review Evidence, Not More Parallelism
Whiteboard visualizes intent, Archify maps systems, and TODO Flow preserves task and review state. Together they show a tool category forming around one problem: proving what coding agents changed and why it is safe to merge.
Whiteboard Turns AI-Generated Code Into a Reviewable System Map
The open-source Code OSS desktop app links agent-drawn architecture, semantic diffs, and decision logs back to source code. Its bet is that understanding—not generation—is now the coding bottleneck.
AI Science Agents Need an Evidence Ladder, Not a Discovery Score
Anthropic's ART result, Google's AI co-scientist, and published laboratory validations show a common pattern: agents can widen hypothesis search, but experiments determine what survives.
Tags
> Stay in the loop
Weekly AI tools & insights.