AI Hardware Fit Makes Local-Model Planning Inspectable—Including the Guesses
The browser-based open-source tool matches 332 AI models with 151 GPU configurations, estimates service capacity and cost, and labels measured, corrected, related, and calculated values instead of presenting every number as a benchmark.
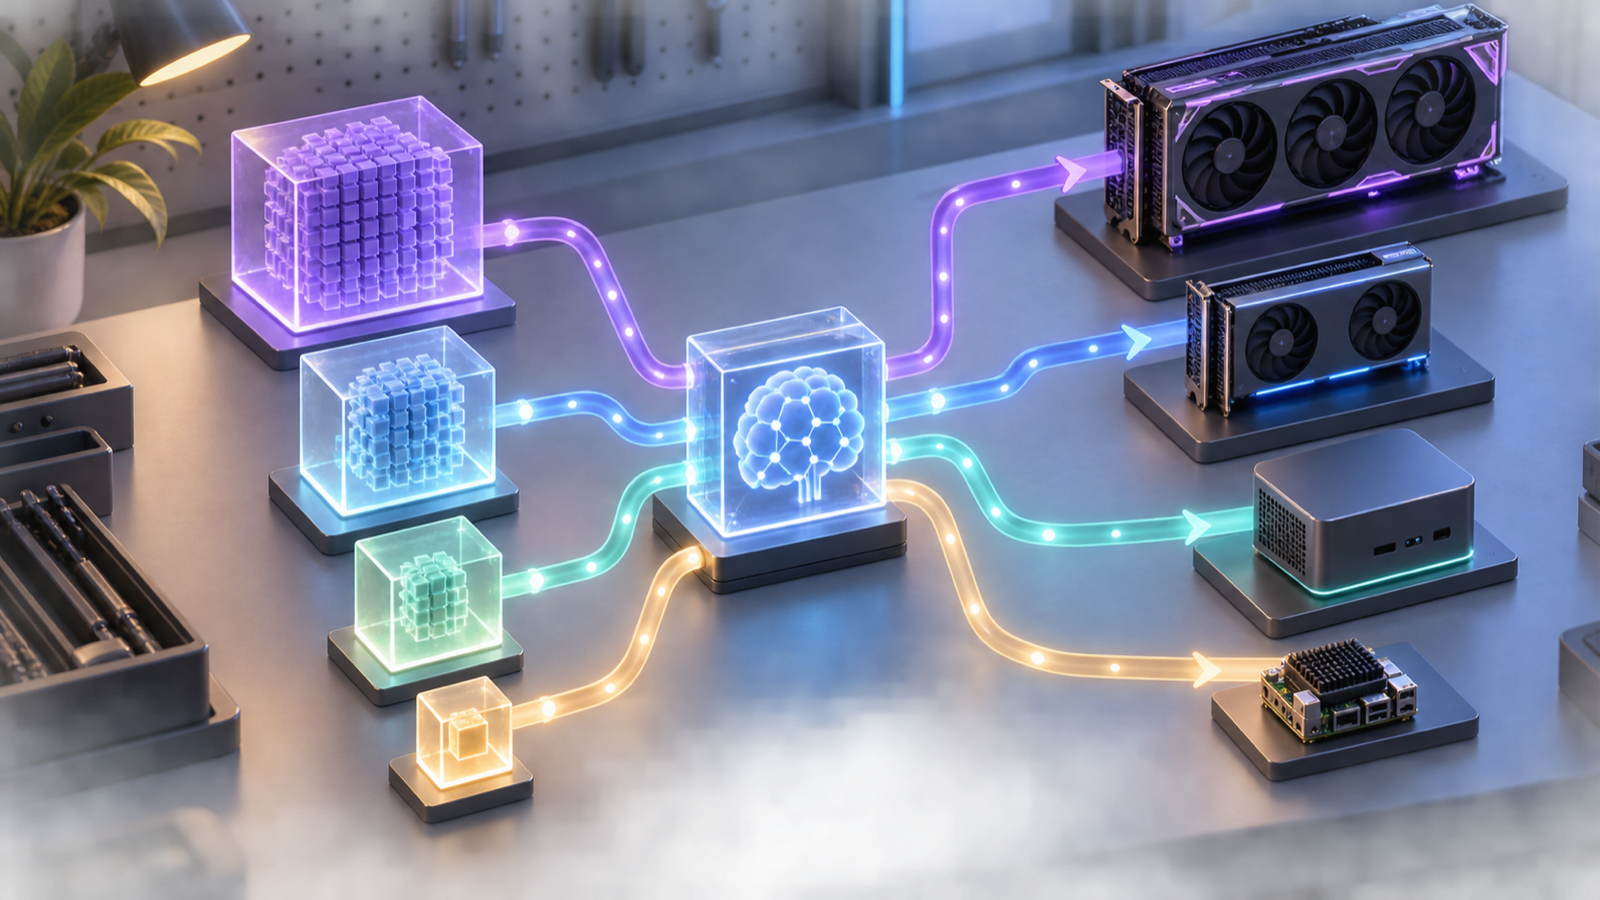
AI Hardware Fit is an open-source browser tool for an increasingly awkward purchasing question: which model can run on a particular machine, and what changes when that machine has to serve other people? It currently lists 151 GPU configurations and 332 AI models, then supports four paths: start with hardware, start with a model, size a shared service, or inspect public benchmarks.
The project appeared on GeekNews on September 28 and had one point when checked at 1:18 p.m. Malaysia time. Its GitHub repository showed 43 stars and a same-day update. Those are early discovery signals, not evidence that its estimates are accurate. The more important design choice is methodological: the interface distinguishes measured values, corrected measurements, related measurements, and calculated estimates.
What happened
The tool’s simplest path lets a user select a GPU and receive three model suggestions with quantization, estimated memory use, speed range, and a run command. The reverse path starts with a model and compares hardware by budget, speed, and power. A service-sizing view accepts user and concurrency assumptions, while advanced views address model placement, API-versus-self-hosted cost, batch document work, and shared hardware.
Everything runs in the browser without an account, according to the project. Its formulas and datasets are stored in the public repository under an MIT license. The author says a recent update changed recommendations to prioritize newer and distilled models, added release date, benchmark, and architecture context, and repaired navigation and bilingual-interface issues.
The project also states that many combinations still depend on estimates. That warning matters because model names do not determine deployment behavior by themselves. Quantization format, context length, key-value cache, batch size, runtime, driver, attention implementation, speculative decoding, and memory fragmentation can change whether a configuration fits and how quickly it responds.
Why it matters
Local AI purchasing advice is usually split across model cards, vendor specifications, benchmark spreadsheets, forum posts, and calculators that hide their assumptions. A single confident “yes, it fits” can conceal an unusable setup: weights may load while the context cache exhausts memory, or throughput may look adequate at batch one and collapse under concurrency.
AI Hardware Fit is valuable because it treats the answer as a planning model. Users can see the difference between a public run and a derived estimate, then adjust assumptions. That makes disagreement actionable. A developer can submit a measurement, inspect a formula, or decide that a number is too uncertain for a purchase.
The service-sizing view is particularly relevant for small teams. Buying one card for an interactive chatbot is not the same problem as sizing document extraction, embeddings, or a multi-user coding service. Latency targets, queueing, duty cycle, electricity, and utilization determine whether a cheap API or owned hardware is economically sensible.
Evidence
The public application exposes its model and GPU counts, methodology links, benchmark sheet, and example scenarios. The GitHub repository contains the code, datasets, data-source notes, and issue tracker. The visible repository metadata showed 43 stars and no forks at our check, which confirms early interest but not operational adoption.
The GeekNews post is authored by the project creator and provides useful change notes. It says the tool supports NVIDIA, AMD, Intel, and Apple Silicon and separates measurement classes. Because it is a launch post, those statements remain first-party. The repository makes them inspectable, but EgoistAI did not independently execute all 50,000-plus possible model-hardware combinations.
The strongest claim the interface can support is relative planning. A vendor specification can establish memory capacity and hardware features. A model file can establish weight size. A measured run can establish performance for one software stack and configuration. Extrapolating beyond that run introduces uncertainty, and the tool appropriately labels that uncertainty rather than turning it into a benchmark badge.
Practical takeaway
Use AI Hardware Fit to create a shortlist, not a purchase order. First specify the actual model build, quantization, target context, batch or concurrency, acceptable first-token latency, sustained throughput, and software runtime. Check whether the selected number is measured or estimated. Then reproduce a representative workload on rented or borrowed hardware before committing capital.
For a shared service, test steady state and bursts. Record peak memory, time to first token, tokens per second, request queue, power, failures, and model quality after quantization. Include operational costs: host memory, storage, network, cooling, engineering time, and idle capacity can dominate the GPU sticker price.
Contributing measured results may be as valuable as using the calculator. A transparent planning tool improves when runs include exact hardware, driver, runtime, model revision, quantization, context, batch, and command. A number without that context is difficult to reuse safely.
Limitations
This is an early project with sparse community validation. Hardware and model releases move quickly, while software optimizations can make an older result stale. Public benchmarks can favor throughput over interactive latency or use settings unlike a real application. Calculated cost depends on electricity, utilization, depreciation, and API pricing assumptions.
The tool cannot decide whether a model is good enough for a task. A configuration that fits may still produce unacceptable output. The useful conclusion is that AI Hardware Fit offers a transparent starting point and a better vocabulary for uncertainty—not that it removes the need for a real workload test.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
Claude Code Left Secrets in 1,122 GitHub Files—Check This Setting
Apiiro traced exposed credentials to Claude Code permission files. The awkward part: approving a command can preserve the password inside your project.
GPT-6 Cyber Can Build Exploits—But Builders Face a Different Test
OpenAI's GPT-6 Cyber pairs stronger exploit research with tighter scope controls. For builders, access rules and reproducible evidence matter as much as benchmarks.
1,122 GitHub Files Exposed Secrets—What Did “Don't Ask Again” Save?
Apiiro found credentials in 1,122 public Claude Code settings files. A saved approval can preserve the password inside a command—and send it into your next commit.
Most Read
- 1 Kimi K3.1 Pro: China's Open-Weight Model Just Caught the Frontier
- 2 OpenAI Is Buying the Bottleneck: Can Orchestra Bio Cut a 15-Year Drug Timeline?
- 3 1,068 Tokens Per Second: Can Mercury 3 Change How LLMs Generate Text?
- 4 Same Price, Better Coding: How Good Is DeepSeek V4.1 Flash 1017?
- 5 Used OpenCode? Should You Rotate Your API Key After the Console Breach?





Latest News
- Claude Code Left Secrets in 1,122 GitHub Files—Check This Setting
- Gemini Omni 1.2 Flash Makes 15-Second Video Cheaper—Then Comes the Edit
- GPT-6 Cyber Can Build Exploits—But Builders Face a Different Test
- 1,122 GitHub Files Exposed Secrets—What Did “Don't Ask Again” Save?
- Gemini Omni 1.2 Flash Offers $1.05 Clips—What Does That Buy You?
- GPT-6 Cyber Hits 48.5% on ExploitGym—Who Gets the Keys?
Tags
> Stay in the loop
Weekly AI tools & insights.