Sparse Models Are Reframing Local AI Economics—but Active Parameters Are Only Half the Bill
Solar Mini 4 and Kolibri show why agent stacks are splitting routine work from frontier reasoning. Their specifications also expose the metrics buyers must not collapse into one number.
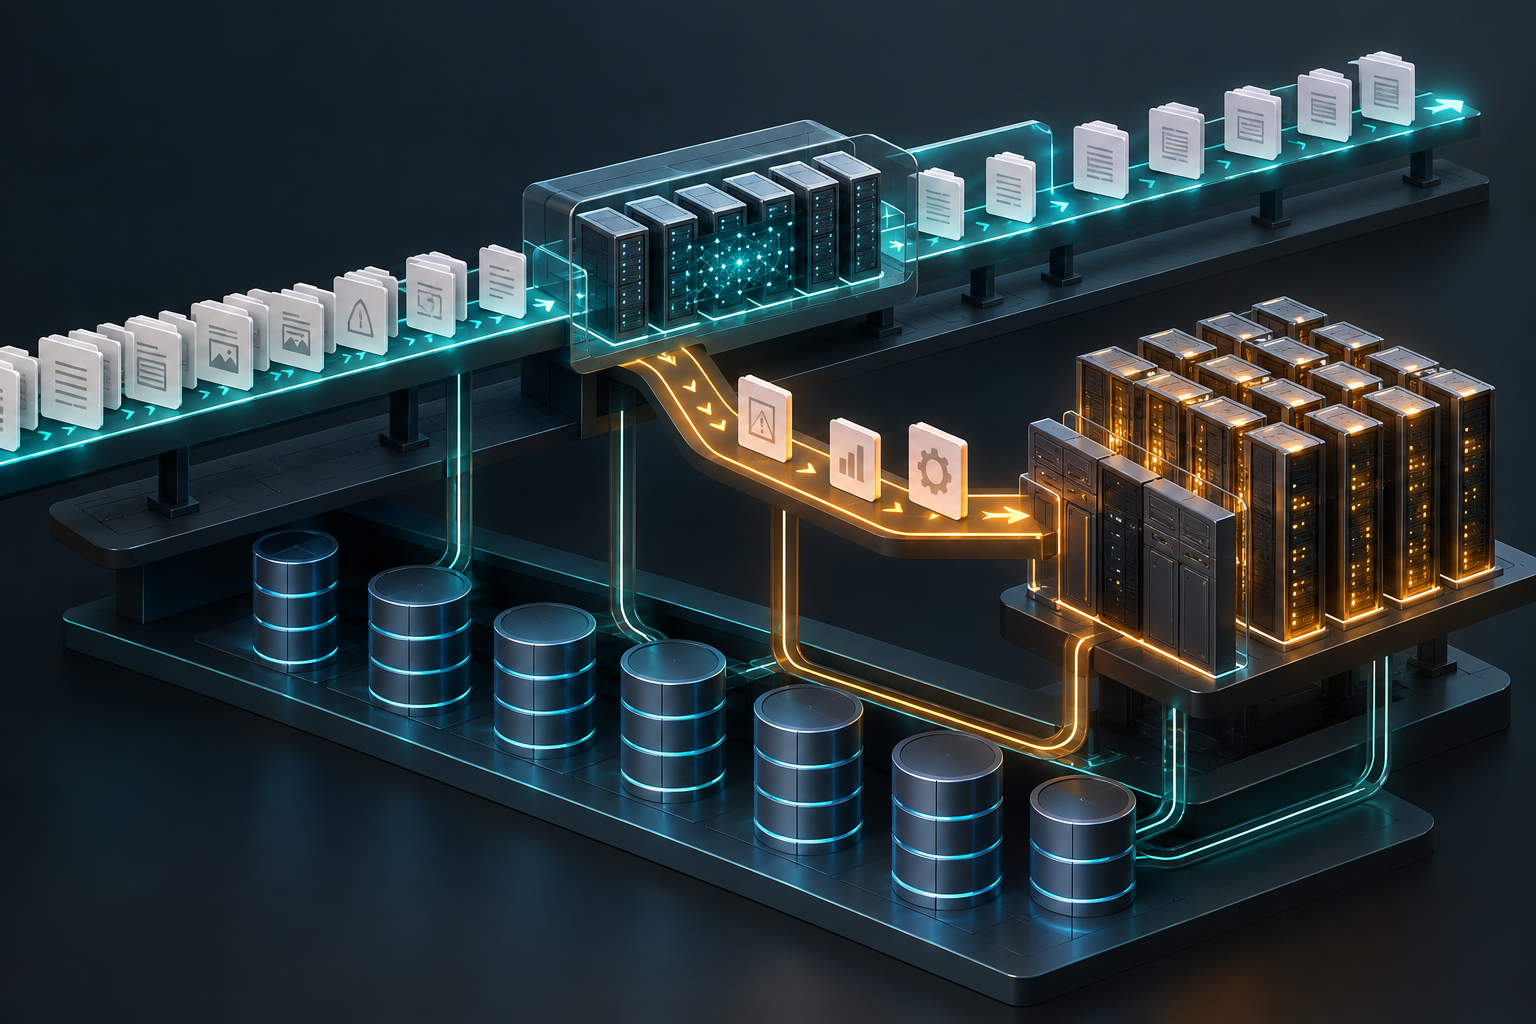
Two releases surfaced by developer communities this weekend point in the same direction. Upstage’s Solar Mini 4 contains roughly 35 billion parameters while activating 3 billion per token. Aleph Alpha’s Kolibri contains 78.1 billion and activates 3.46 billion. Both use sparse mixture-of-experts architectures to spend less computation per generated token than a dense model of the same total size.
The tempting conclusion is that each behaves economically like a 3B model. That is wrong in a useful way. Active parameters help explain compute. Total parameters help explain weight storage and memory. Context length affects key-value cache. Concurrency changes batching and cache pressure. Output length, quantization, interconnects, serving software, and utilization determine the actual bill.
The deeper shift is organizational: agent systems are beginning to buy capabilities by task rather than one model by reputation.
Three numbers that should never be collapsed
Total parameters describe the model’s stored capacity. A sparse model generally needs access to all expert weights even though a token visits only some experts. This is why Solar Mini 4’s one-H100 claim refers to a quantized model, and why Kolibri’s small active footprint does not make its 78.1B weights disappear.
Active parameters approximate how much expert computation is used for one token. They help explain why a sparse model can provide more stored specialization than a similarly expensive dense forward pass. Routing, expert imbalance, communication, and implementation efficiency still affect realized speed.
Context and concurrency create a separate memory problem. A model that accepts hundreds of thousands of tokens can consume substantial cache memory, especially across simultaneous users. Maximum context is therefore a compatibility ceiling, not a recommended production default.
An honest capacity plan keeps all three numbers visible.
The new agent stack is a queue, not a single brain
Solar Mini 4 is positioned for extraction, classification, structured output, and tool calls. Kolibri emphasizes English–German work, controlled deployment, long documents, and regulated settings. Neither launch needs to prove that one small-active model is best at every intellectual task. Their economic value appears when a workflow routes tasks.
A contract pipeline might use deterministic parsing first, a sparse model to classify clauses and populate a schema, retrieval to supply policy text, and a larger reasoning model only when confidence is low or provisions conflict. A human remains responsible for consequential review. The savings come from the distribution of work: most items follow the cheap path, while exceptions receive more computation and oversight.
This architecture is also more measurable. Classification accuracy, schema validity, abstention, escalation rate, and tool-call success are easier to audit than a vague instruction to “handle the case.”
Where the apparent savings can disappear
Poor utilization is the first trap. A purchased GPU that waits idle may cost more than an API even when its marginal token cost looks low. High availability can require a second device. Engineering time, monitoring, security patches, and model upgrades are part of total cost.
Retries are the second trap. A cheap model that produces invalid JSON, chooses the wrong tool, or misses a field can trigger extra calls and human correction. Cost per successful task is more useful than cost per million tokens.
Long context is the third trap. Loading an entire archive into a prompt can be slower, less reliable, and more expensive than retrieval. Both new models advertise large windows, but neither specification removes the need for source selection and provenance.
Benchmark overfitting is the fourth trap. Upstage cites automation and banking-agent benchmarks. Aleph Alpha publishes extensive English, German, coding, math, industrial, and agent results. These are evidence, but a buyer’s workflow may differ in language, document noise, policy ambiguity, and error cost. Independent leaderboards such as Artificial Analysis or LM Arena add outside views, yet they still do not replace a private acceptance test.
A deployment scorecard
Start with quality: exact-field accuracy, tool-choice precision and recall, groundedness, calibration, and failure severity. Add economics: input and output tokens, cache use, latency percentiles, GPU utilization, retries, escalations, and human minutes. Add governance: license, data location, retention, administrator access, model provenance, and rollback.
Run at least three baselines: deterministic rules where possible, the candidate sparse model, and the larger model currently used. Test a routed system rather than comparing only isolated prompts. Freeze a held-out set before tuning, and include malicious or malformed inputs that try to redirect tool use.
For self-hosting, test the exact quantization and serving engine. Report cold start, steady-state throughput, memory at the 95th-percentile context, and behavior when a worker fails. For API use, test rate limits and provider-side feature parity rather than assuming that every host exposes the same tool or context behavior.
The strategic takeaway
Sparse models do not make capacity free. They make the allocation problem more interesting. The winning design is likely to treat models as a portfolio: rules for deterministic steps, small or sparse models for bounded repetition, specialized models for language or domain needs, and frontier models for genuinely difficult exceptions.
Solar Mini 4 and Kolibri matter because their releases make that portfolio easier to assemble under different constraints. One emphasizes inexpensive agent operations and a one-GPU quantized target. The other combines open weights, bilingual optimization, detailed technical documentation, and controlled deployment. The buyer’s job is to map those properties to a measured queue of work—not to crown a universal winner from an active-parameter count.
Limitations
Both models were newly released, so independent replications and long-running production reports were limited. Vendor benchmark results use selected configurations. API prices, third-party availability, and model revisions may change. This analysis does not estimate a universal break-even point because hardware price, utilization, staffing, workload shape, and error cost vary too widely.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
Aleph Alpha Releases Kolibri as an Apache-2.0 English–German MoE Model
Kolibri activates 3.46B of 78.1B parameters per token, publishes weights under Apache 2.0, and makes data control, German efficiency, and deployment cost part of the model specification.
Solar Mini 4 Targets Repetitive Agent Work With 3B Active Parameters
Upstage's new sparse model combines a 35B-parameter footprint with 3B active parameters per token, structured output, parallel tool calls, and a one-H100 quantized deployment target.
AI Products Are Splitting Into Three Layers: Belief, Composition, and Deployment
Ataraxos, FLUX 3 Image, and ChatGPT Sites look unrelated. Together they show a shift from one-shot model outputs toward explicit intermediate state that people and agents can inspect.
Tags
> Stay in the loop
Weekly AI tools & insights.