LLM Timeout Budget Propagation: Stop Nested AI Calls From Outliving the User Request
One slow model call can trigger a chain of zombie retries. Propagate a shared deadline through agents, tools, queues, and providers to bound latency.
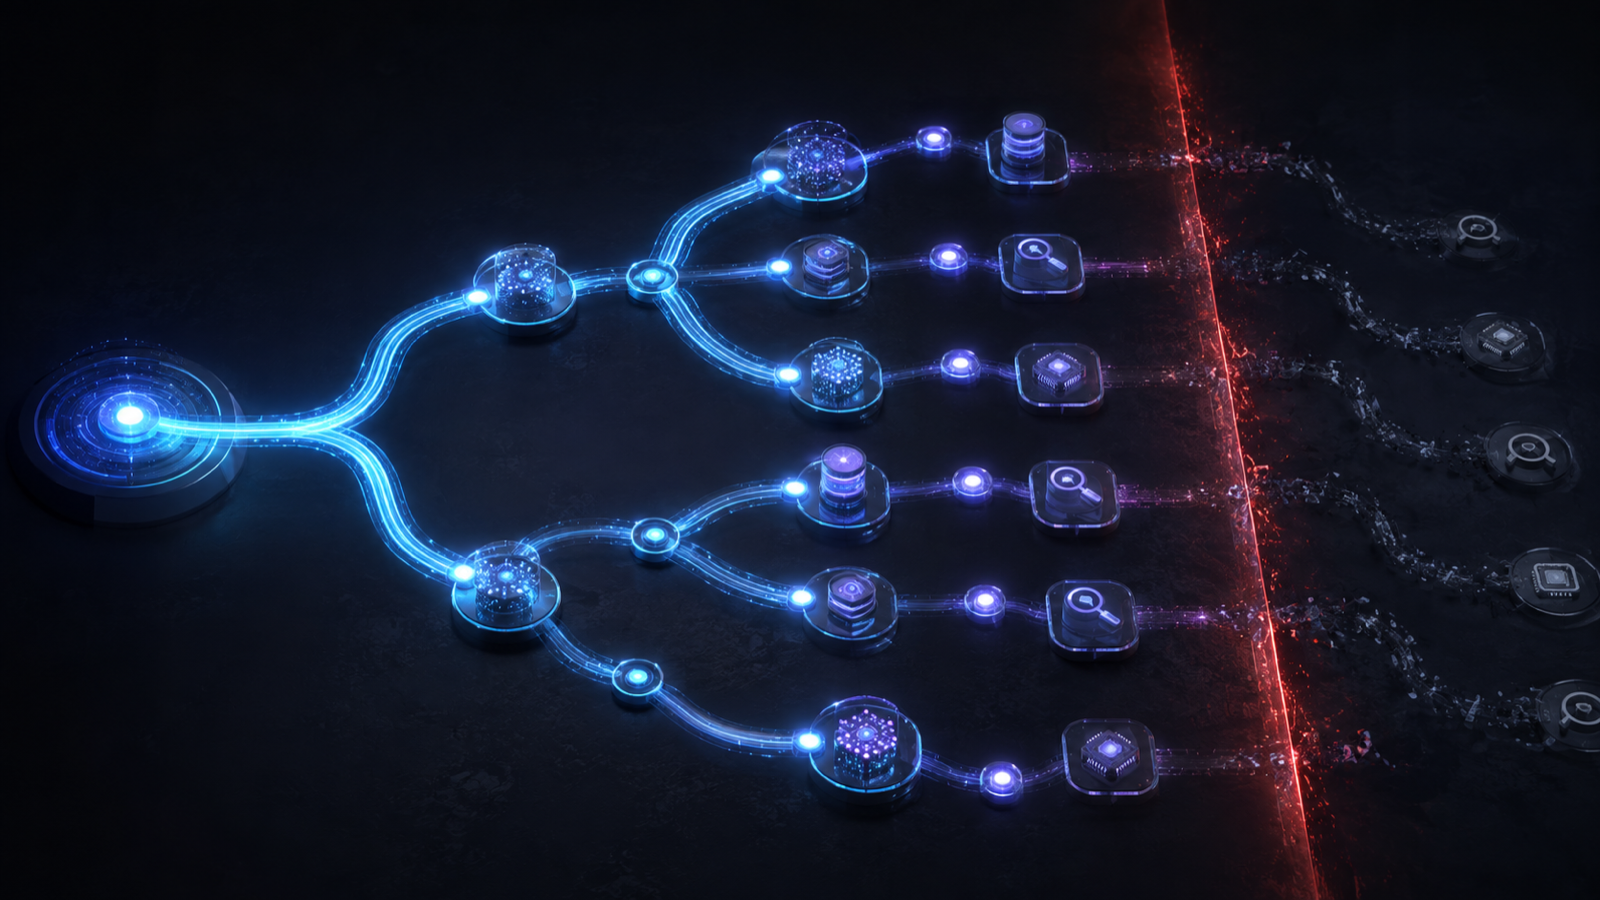
A 30-second request cannot safely contain three independent 30-second calls. Without LLM timeout budget propagation, nested agents and tools continue working after the caller has given up, consuming tokens, holding locks, and sometimes committing effects nobody is waiting to see.
The solution is a shared absolute deadline. Each component spends from the same budget, reserves time for cleanup, and refuses to start work it cannot plausibly finish.
Prerequisites
Your request context needs a monotonic clock, an absolute deadline, cancellation signaling, and instrumentation around provider calls. Use wall-clock timestamps for cross-service metadata, but calculate local remaining time with a monotonic source so clock adjustments do not create negative or extended budgets.
Step 1: establish one deadline
At the edge, translate the product latency target into an absolute deadline.
type Budget = {
  deadlineEpochMs: number;
  requestId: string;
  cancelled: AbortSignal;
};

const budget: Budget = {
  deadlineEpochMs: Date.now() + 30_000,
  requestId: crypto.randomUUID(),
  cancelled: requestAbort.signal,
};
Propagate the deadline, not “30 seconds remaining.” Relative durations become inaccurate in queues and network transit.
Step 2: reserve completion time
Before each operation, calculate usable time.
function usableMs(b: Budget, reserveMs = 1500) {
  return Math.max(0, b.deadlineEpochMs - Date.now() - reserveMs);
}

const remaining = usableMs(budget);
if (remaining < 800) throw new DeadlineExceeded("not enough time to start model call");
The reserve lets you persist state, release leases, write traces, and return a coherent partial result. A timeout that leaves no cleanup window creates corrupt workflow state.
Step 3: cap every child call
Provider SDK timeouts must be the minimum of the remaining budget and the operation’s own safe maximum.
const timeoutMs = Math.min(usableMs(budget), 12_000);
const controller = new AbortController();
const timer = setTimeout(() => controller.abort(), timeoutMs);

try {
  return await llm.responses.create({
    model: selectedModel,
    input,
    signal: AbortSignal.any([controller.signal, budget.cancelled]),
  });
} finally {
  clearTimeout(timer);
}
Apply the same rule to retrieval, database queries, browser calls, and tool execution. One uncapped dependency defeats the architecture.
Step 4: budget retries before the first attempt
Retries multiply tail latency. Decide the maximum attempts and per-attempt caps while considering backoff.
for (let attempt = 1; attempt <= 3; attempt++) {
  const remaining = usableMs(budget);
  const futureBackoff = attempt < 3 ? 250 * 2 ** (attempt - 1) : 0;
  if (remaining < 1000 + futureBackoff) break;

  try {
    return await callProvider({ timeoutMs: Math.min(8000, remaining - futureBackoff) });
  } catch (err) {
    if (!isRetryable(err)) throw err;
    await sleepWithJitter(futureBackoff, budget.cancelled);
  }
}
Never retry validation errors, authentication failures, or policy denials. For rate limits, honor Retry-After only when it fits the shared deadline.
Step 5: propagate through queues
A queued job must carry deadlineEpochMs. Workers should discard or mark expired jobs before expensive setup.
if (Date.now() >= job.deadlineEpochMs - 1000) {
  return jobs.expire(job.id, "deadline elapsed before execution");
}
Expiration is not cancellation of an already committed effect. Side-effecting jobs need idempotency keys and explicit state checks in addition to time budgets.
Step 6: use phase budgets
Reserve fractions for major phases rather than letting planning consume everything. A 30-second interactive request might allocate 4 seconds to routing, 8 to retrieval, 14 to generation, and 4 to validation and response.
These are caps, not quotas. Unused time can flow forward, but later phases retain their minimum reserve. For agent workflows, keep human approval outside an interactive deadline by checkpointing and resuming under a new budget.
Step 7: degrade deliberately
When time is low, reduce optional work in a defined order: skip extra reranking, use a smaller context, request a shorter answer, omit nonessential enrichment, or return a partial result with a continuation token. Do not silently skip authorization or final verification.
Model routing can use the budget too. A faster model may be appropriate when only a few seconds remain, but log that choice and maintain the same safety constraints.
Observability that finds leaks
Record initial budget, queue delay, per-call timeout, attempt count, cancellation reason, time remaining at each boundary, and whether work continued after caller disconnect.
Create alerts for negative remaining time, child timeouts larger than parent budgets, high retry amplification, expired jobs that still execute, and provider completions arriving after the response closed.
Trace visualizations should show the deadline as a vertical boundary. Spans crossing it are immediate candidates for cancellation bugs.
Common pitfalls
Independent service timeouts add rather than constrain. Relative timeouts drift across queues. Cancellation tokens that are created but never passed to the SDK are decorative. Retrying at every layer creates multiplicative storms. Finally, aborting a client request does not guarantee the provider stopped computing, so provider-side timeout controls and idempotent effects still matter.
Expected production behavior
When the budget is healthy, the full pipeline runs. As it shrinks, optional enrichment drops. Once the minimum safe window is gone, no new expensive call begins. State is checkpointed, leases are released, and the caller receives either a verified result or a precise timeout—not a zombie workflow.
Deadlines are a reliability boundary. Propagate one budget through every nested AI call, and the system’s worst-case behavior becomes something you can measure, test, and control.
Sources
> Want more like this?
Get the best AI insights delivered weekly.
By subscribing, you agree to our Privacy Policy. You can unsubscribe at any time.
> Related Articles
pgvector Can Return 4 of Your 10 Matches—Where Did the Rest Go?
A filtered vector search can quietly starve your AI app of evidence. pgvector has a fix, but builders need to measure recall and latency before trusting it.
Agent Memory Consolidation Scheduling: When to Merge, Summarize or Forget
Your agent doesn't need more memory — it needs a maintenance schedule. Here's how to build merge, summarize, and decay policies that keep long-term agents sharp instead of senile.
LLM Output Schema Evolution: Migrating Producers and Consumers Without a Flag Day
Your JSON schema will change. Here's how to evolve LLM output contracts safely — with dual readers, shadow validation, and staged rollouts instead of a risky big-bang cutover.
Most Read
- 1 Kimi K3.1 Pro: China's Open-Weight Model Just Caught the Frontier
- 2 OpenAI Is Buying the Bottleneck: Can Orchestra Bio Cut a 15-Year Drug Timeline?
- 3 1,068 Tokens Per Second: Can Mercury 3 Change How LLMs Generate Text?
- 4 Same Price, Better Coding: How Good Is DeepSeek V4.1 Flash 1017?
- 5 Used OpenCode? Should You Rotate Your API Key After the Console Breach?





Latest News
- Claude Code Left Secrets in 1,122 GitHub Files—Check This Setting
- Gemini Omni 1.2 Flash Makes 15-Second Video Cheaper—Then Comes the Edit
- GPT-6 Cyber Can Build Exploits—But Builders Face a Different Test
- 1,122 GitHub Files Exposed Secrets—What Did “Don't Ask Again” Save?
- Gemini Omni 1.2 Flash Offers $1.05 Clips—What Does That Buy You?
- GPT-6 Cyber Hits 48.5% on ExploitGym—Who Gets the Keys?
Tags
> Stay in the loop
Weekly AI tools & insights.